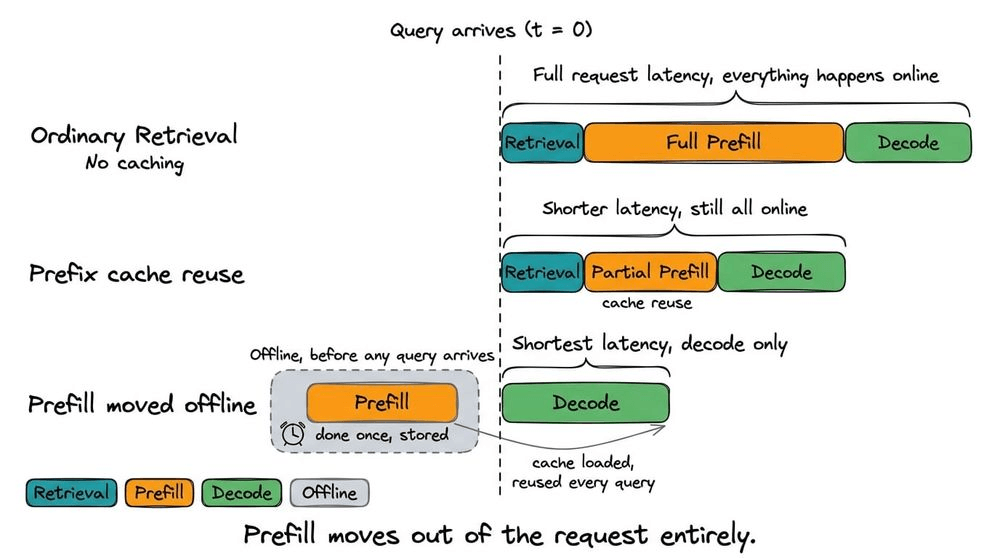
Preloading Knowledge Into a Model Instead of Retrieving It
How to process your corpus once, skip retrieval entirely, and serve every query from a stored cache. Three parts covering the full spectrum.
Lire
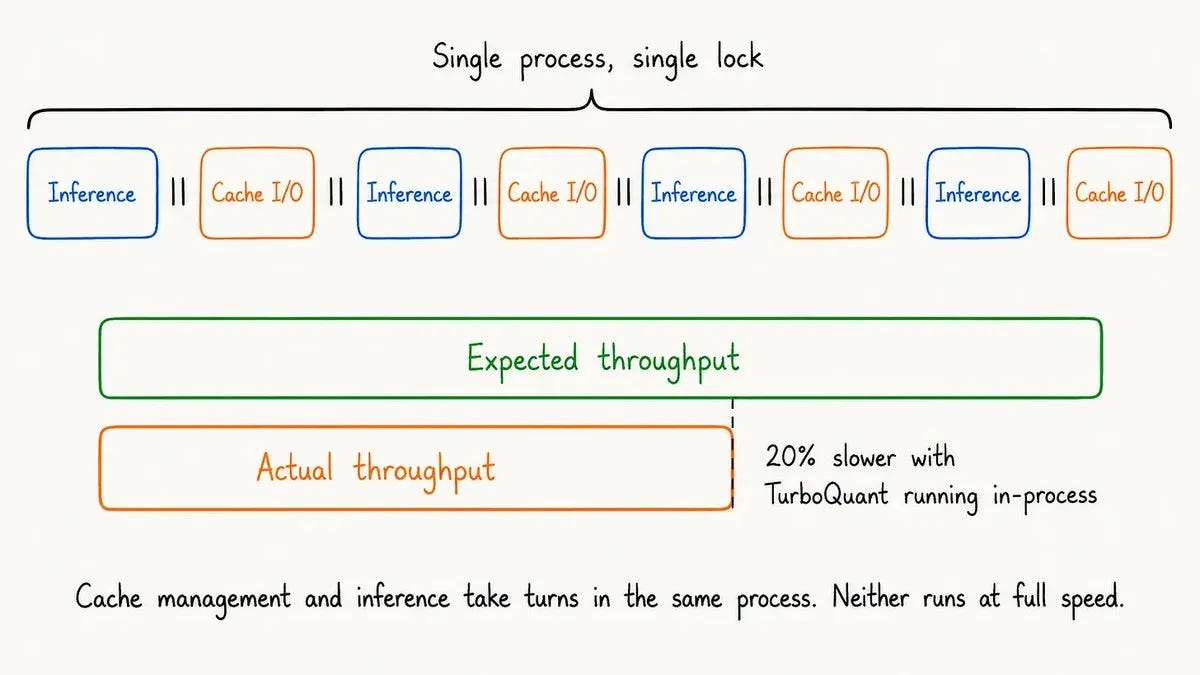
How Semantic Code Navigation Cuts Agent Token Costs by up to 36%
Understanding what an agent actually does with the tokens before it writes code.
Lire
Kimi K3's Sandbox Problem Finally Has an Open-Source Fix
...explained with code.
Lire
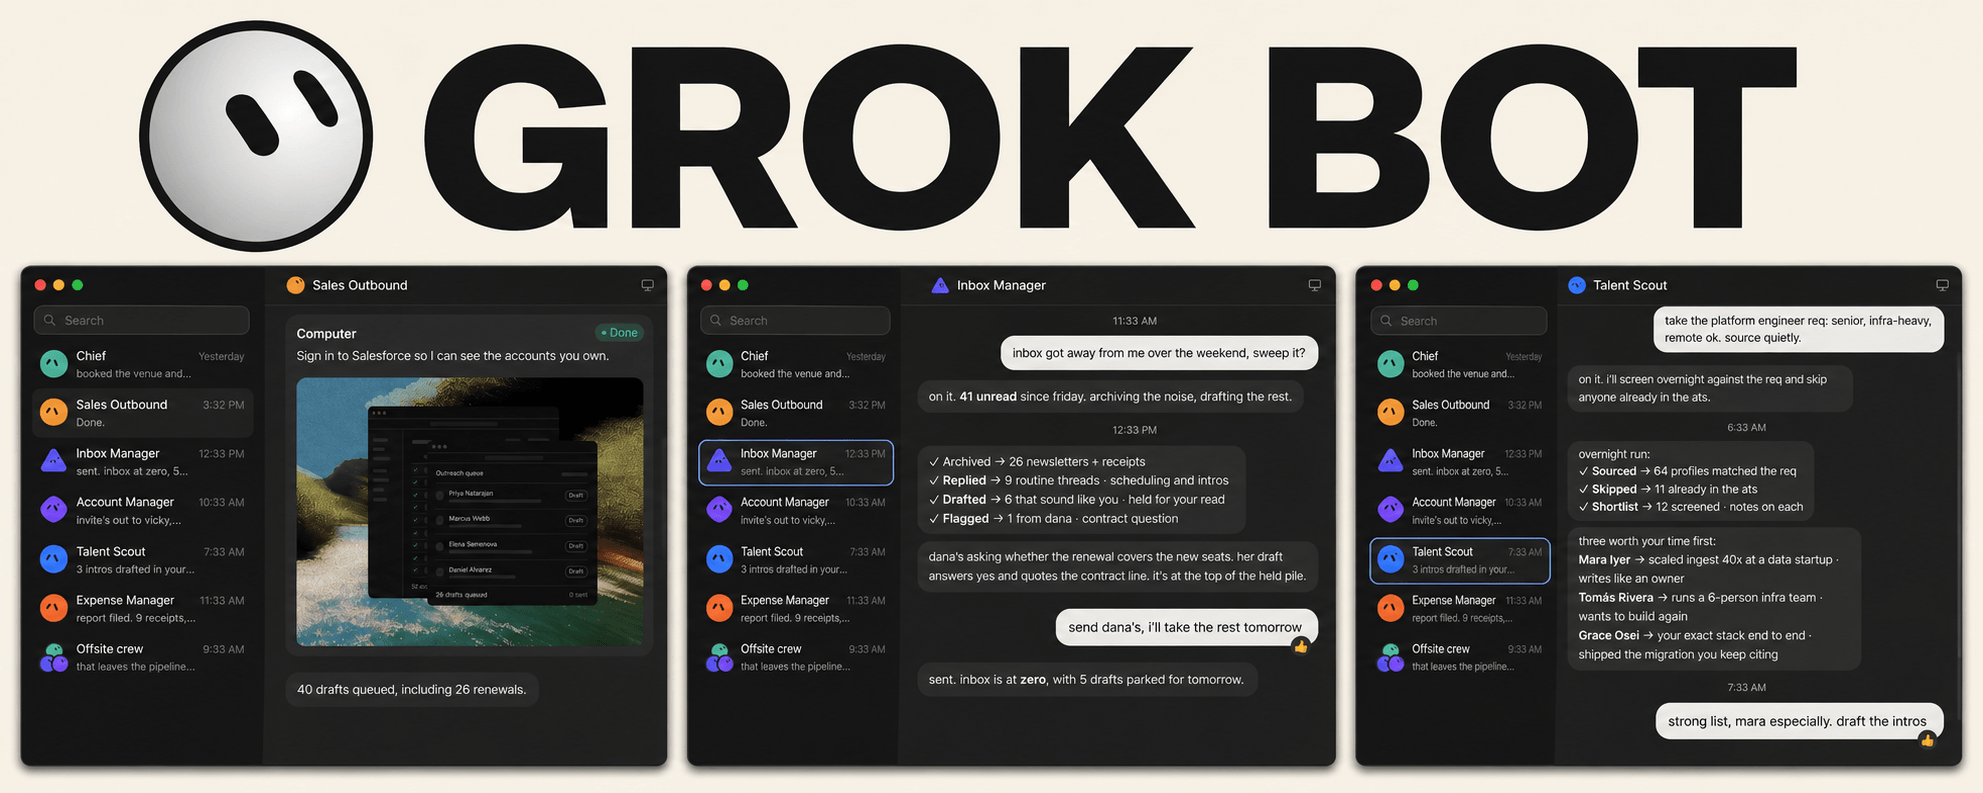
Grok Bot Masterclass
Everything you need to understand, set up, and get real work out of Grok Bot.
Lire
How a GPU Actually Works
The intuition an LLM engineer needs. Understand techniques like quantization, speculative decoding, and continuous batching in one place.
Lire
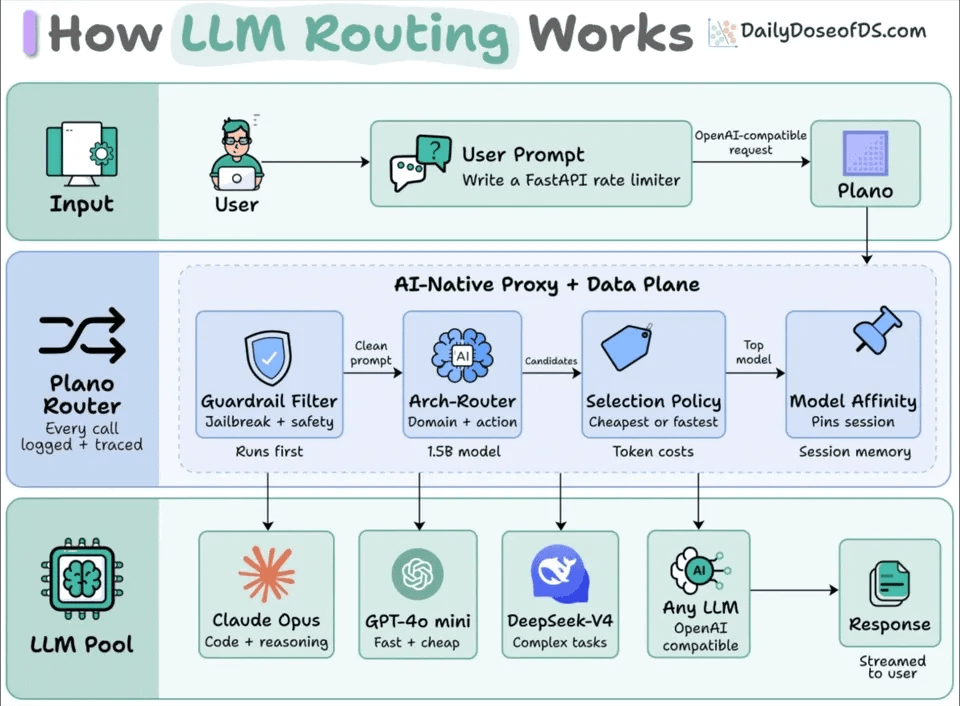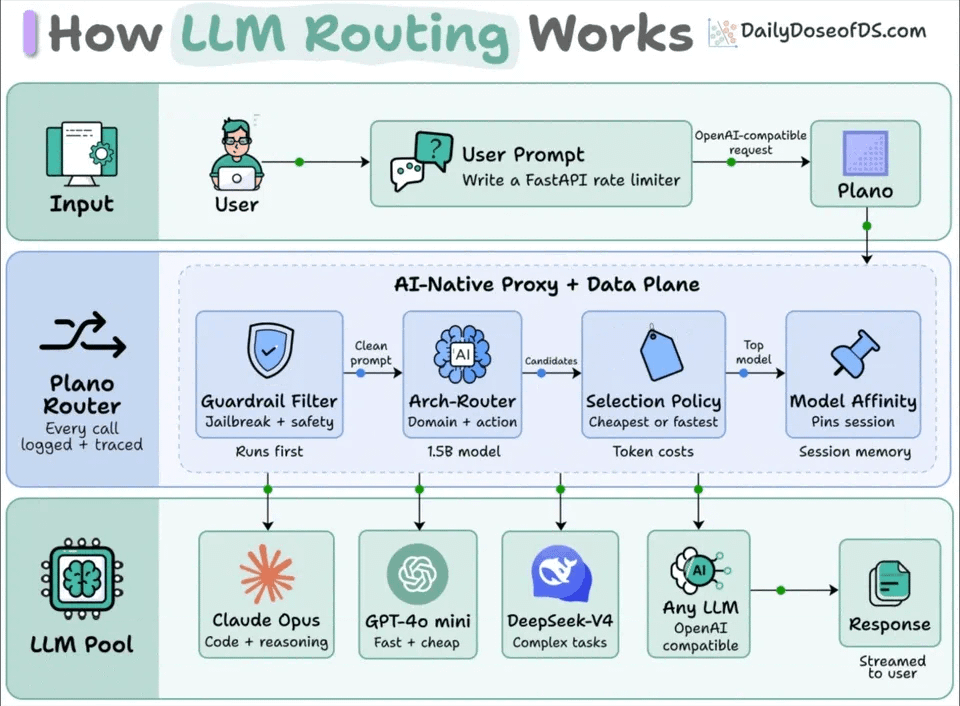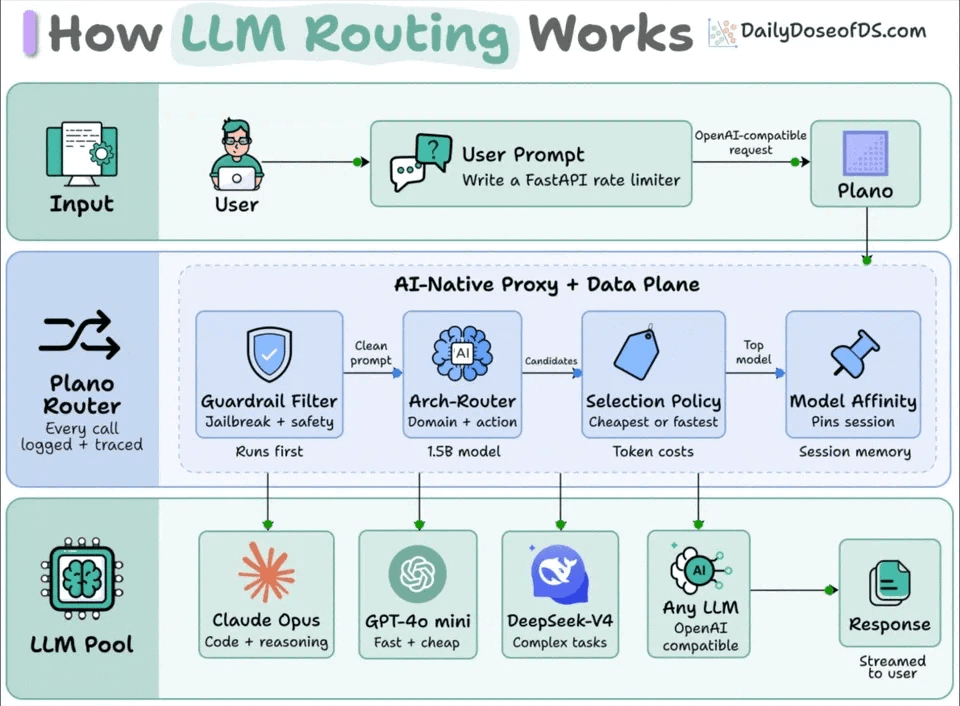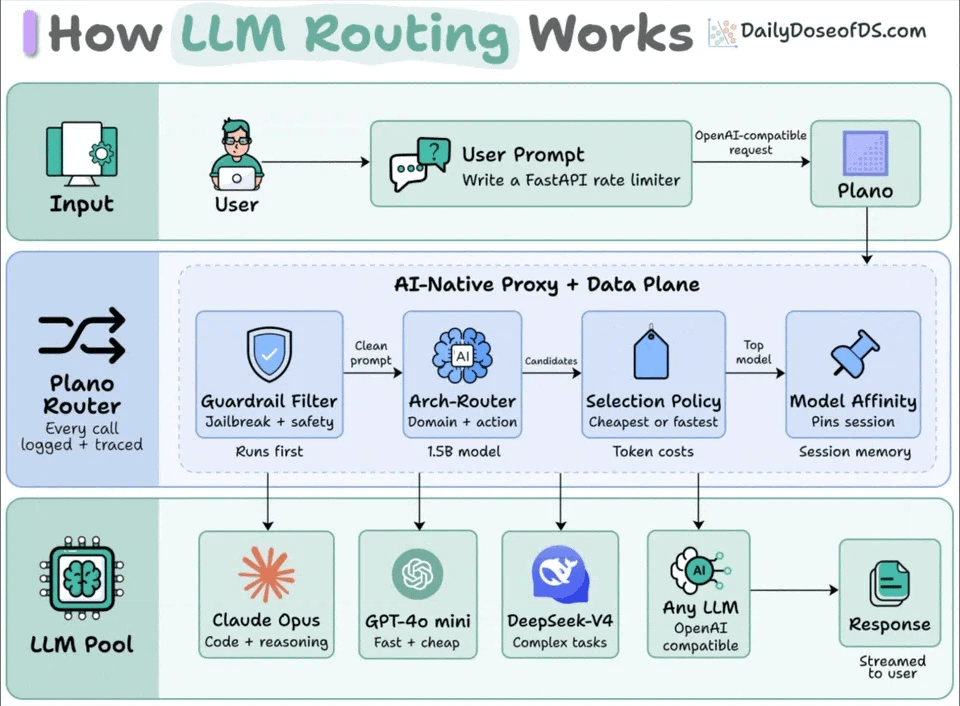
A Cheaper Model Does Not Imply a Cheaper Turn
The practical implications of model routing, clearly explained.
Lire
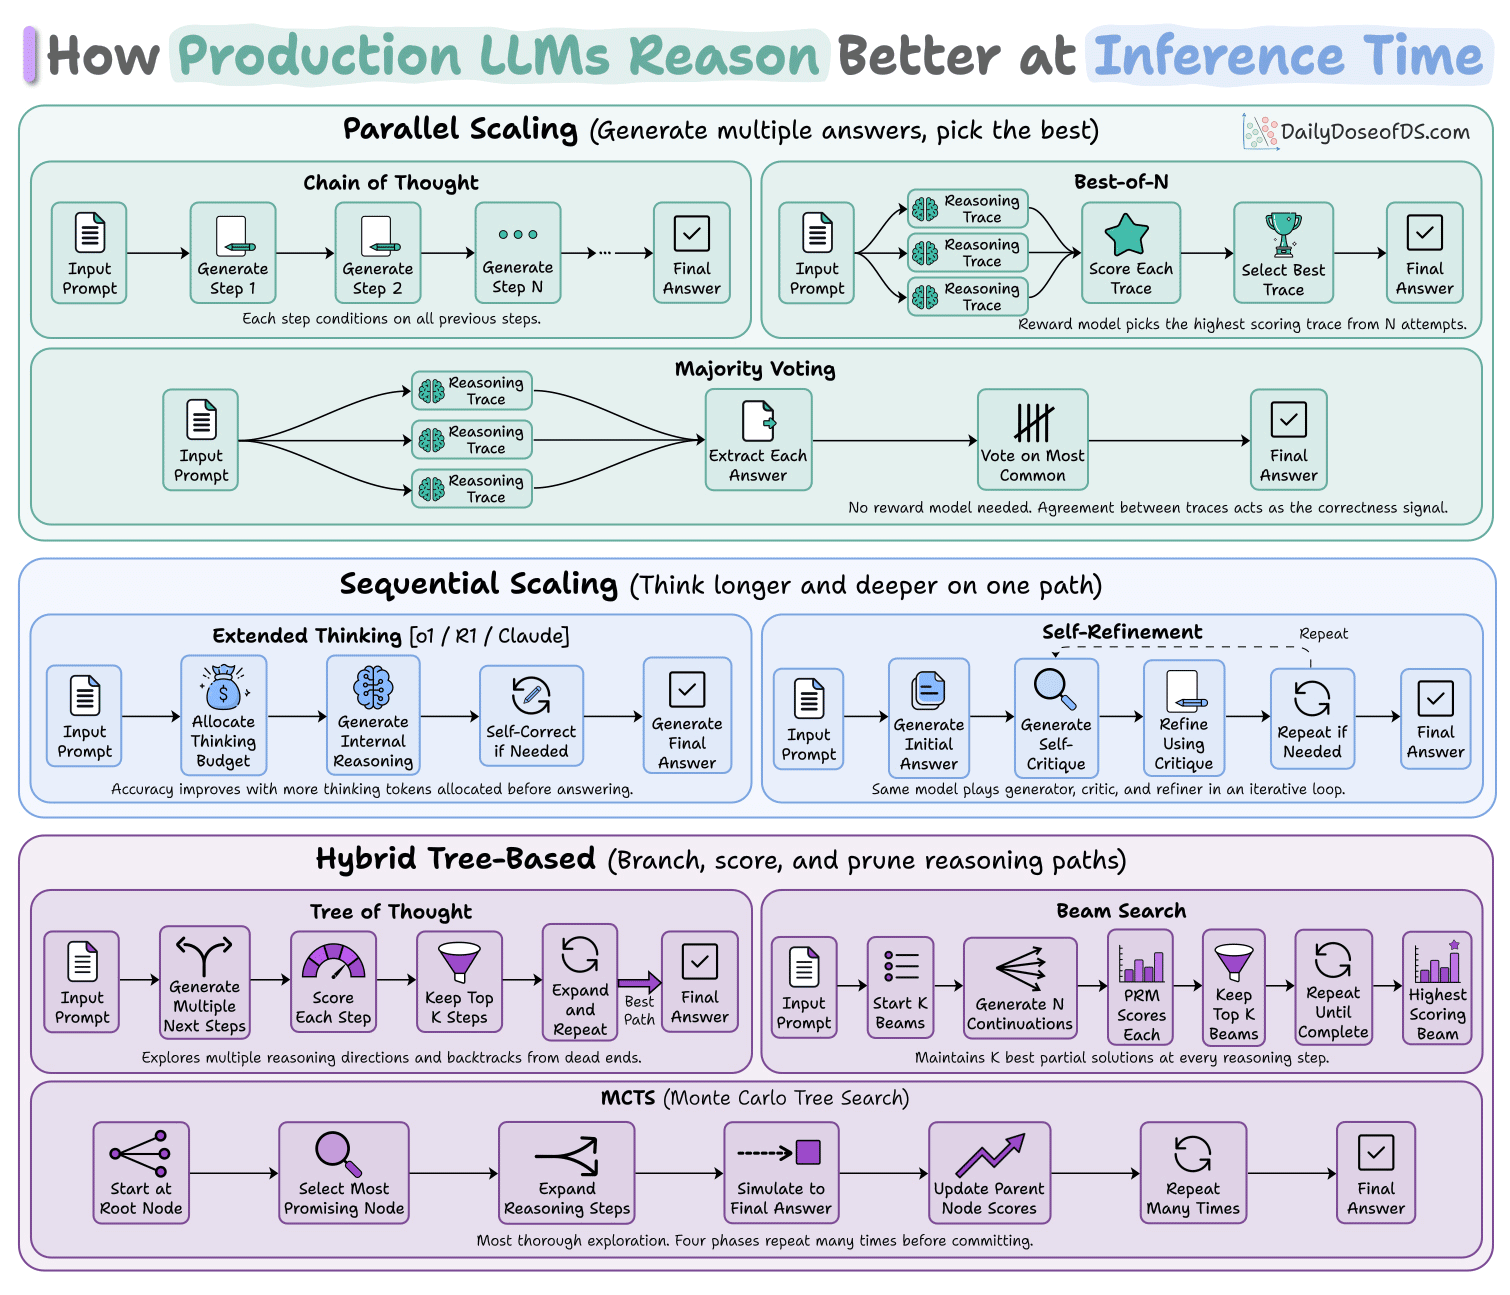
How Production LLMs Reason Better At Inference Time
8 techniques, explained visually.
Lire
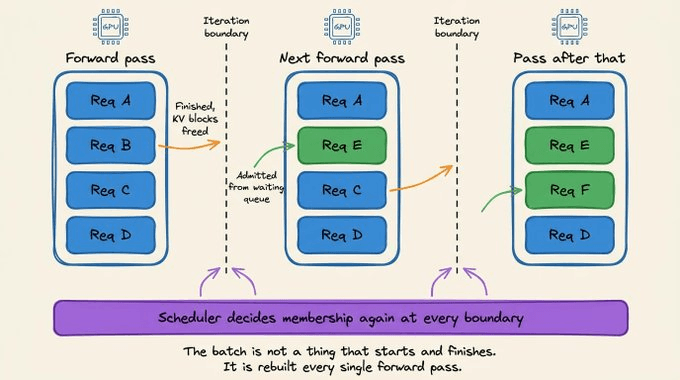
Continuous Batching in LLMs
The technique behind vLLM's 23x throughput jump and the default scheduler in every serving engine.
Lire
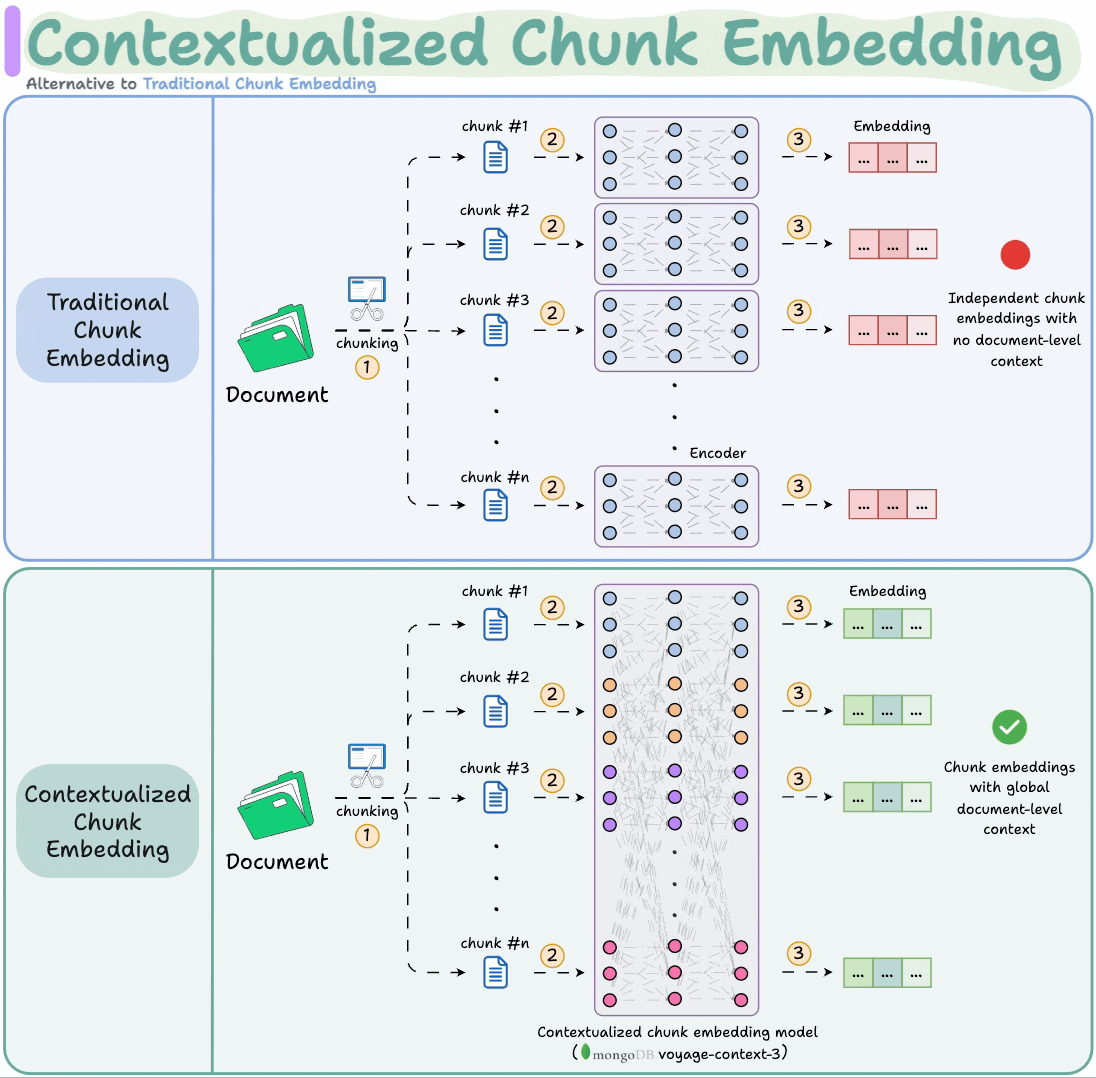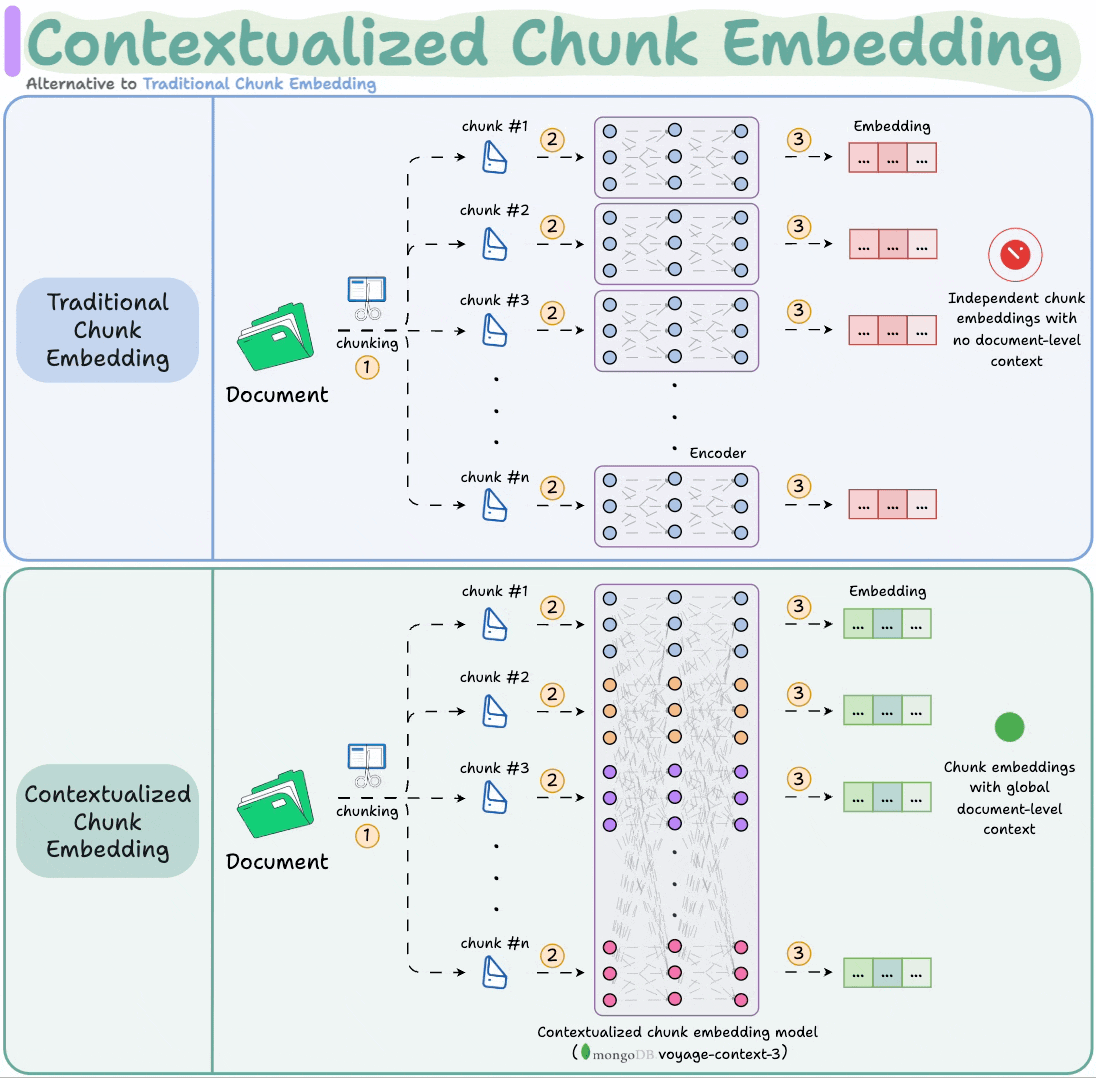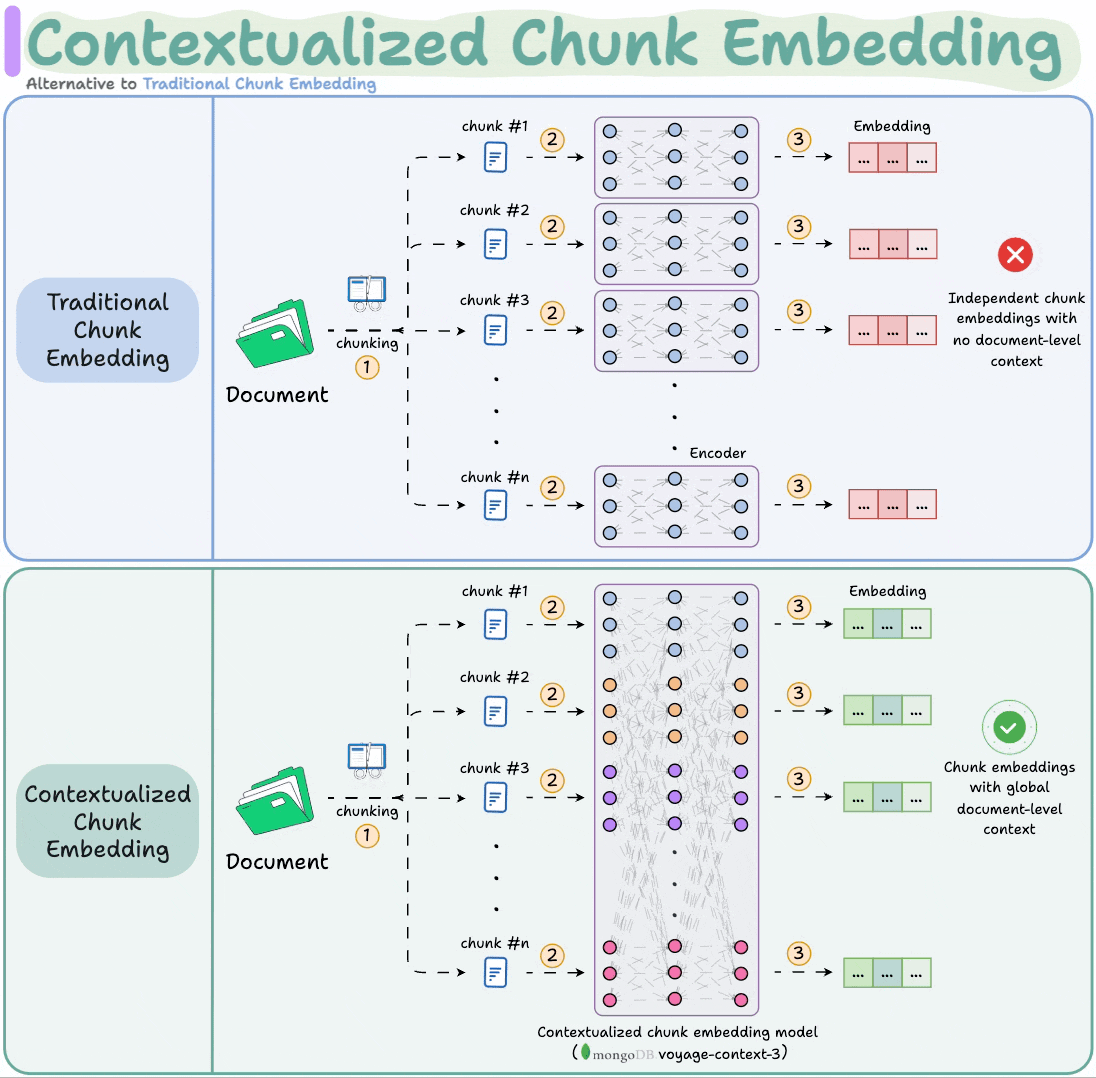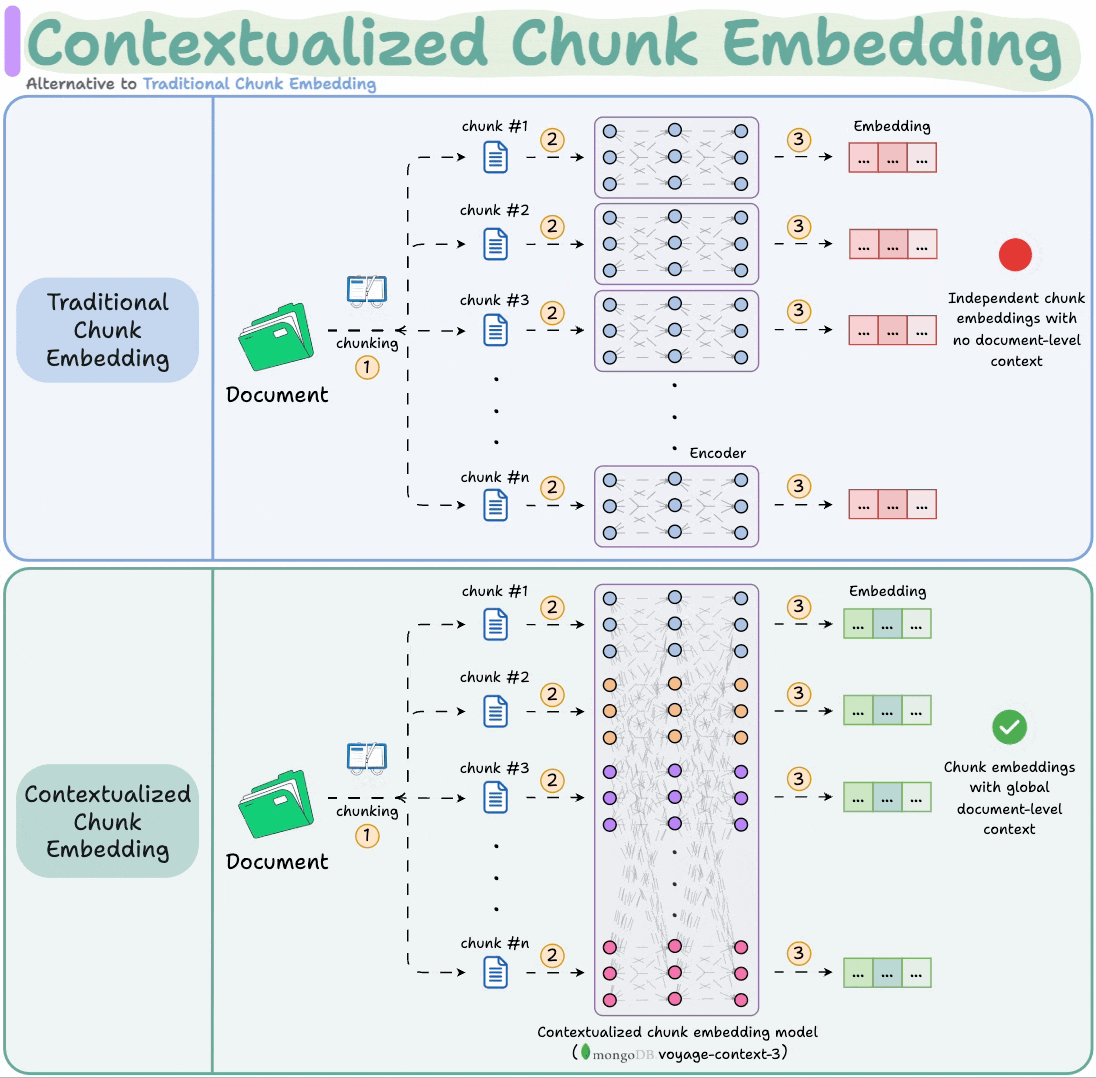
[Hands-on] Audio RAG with 200x Cheaper Vector DB Costs
...while also outperforming OpenAI and Cohere.
Lire
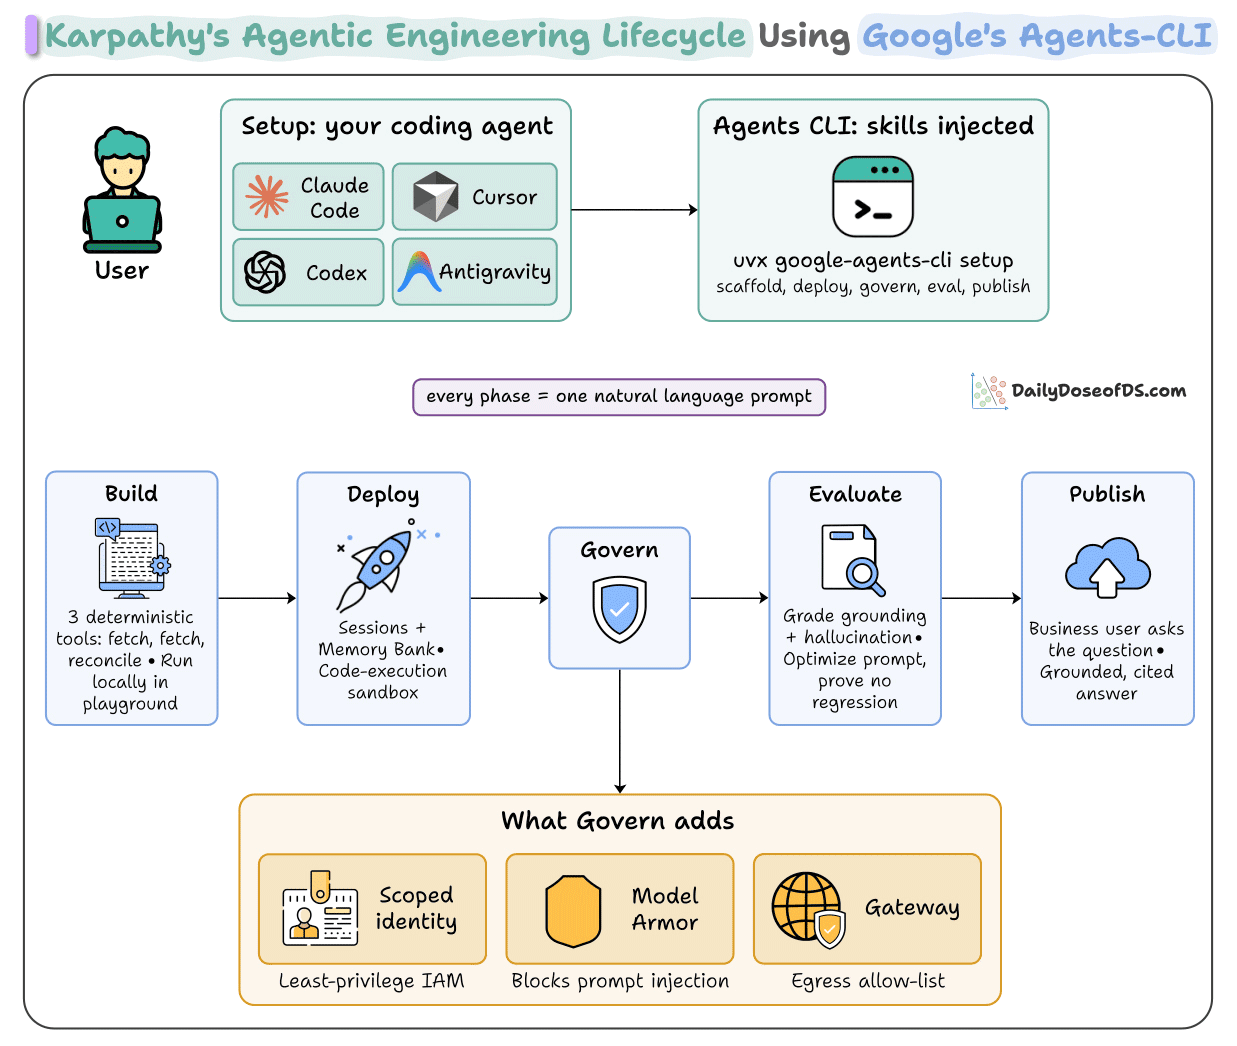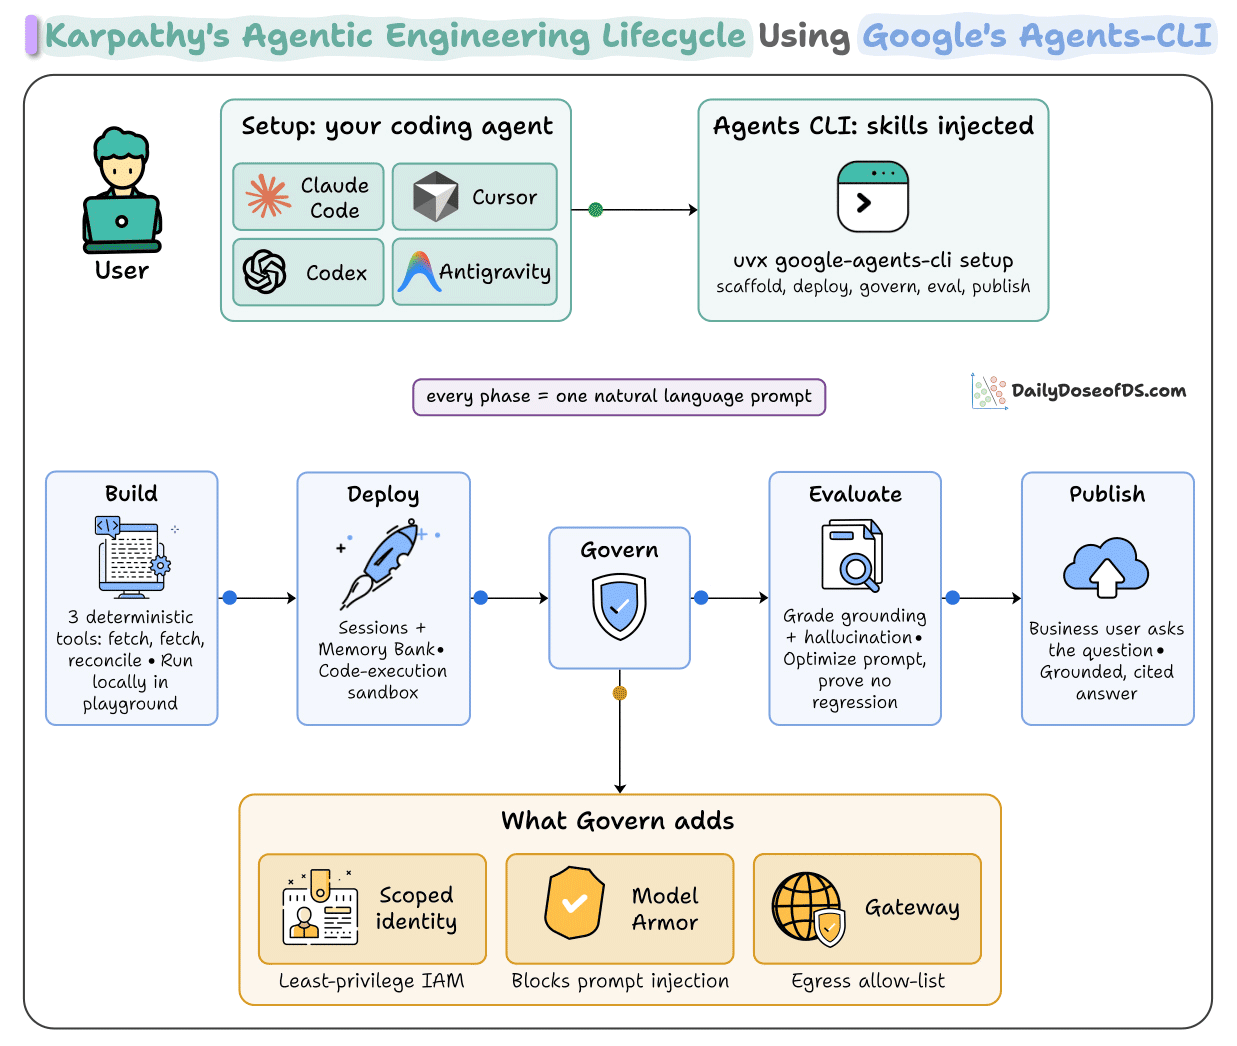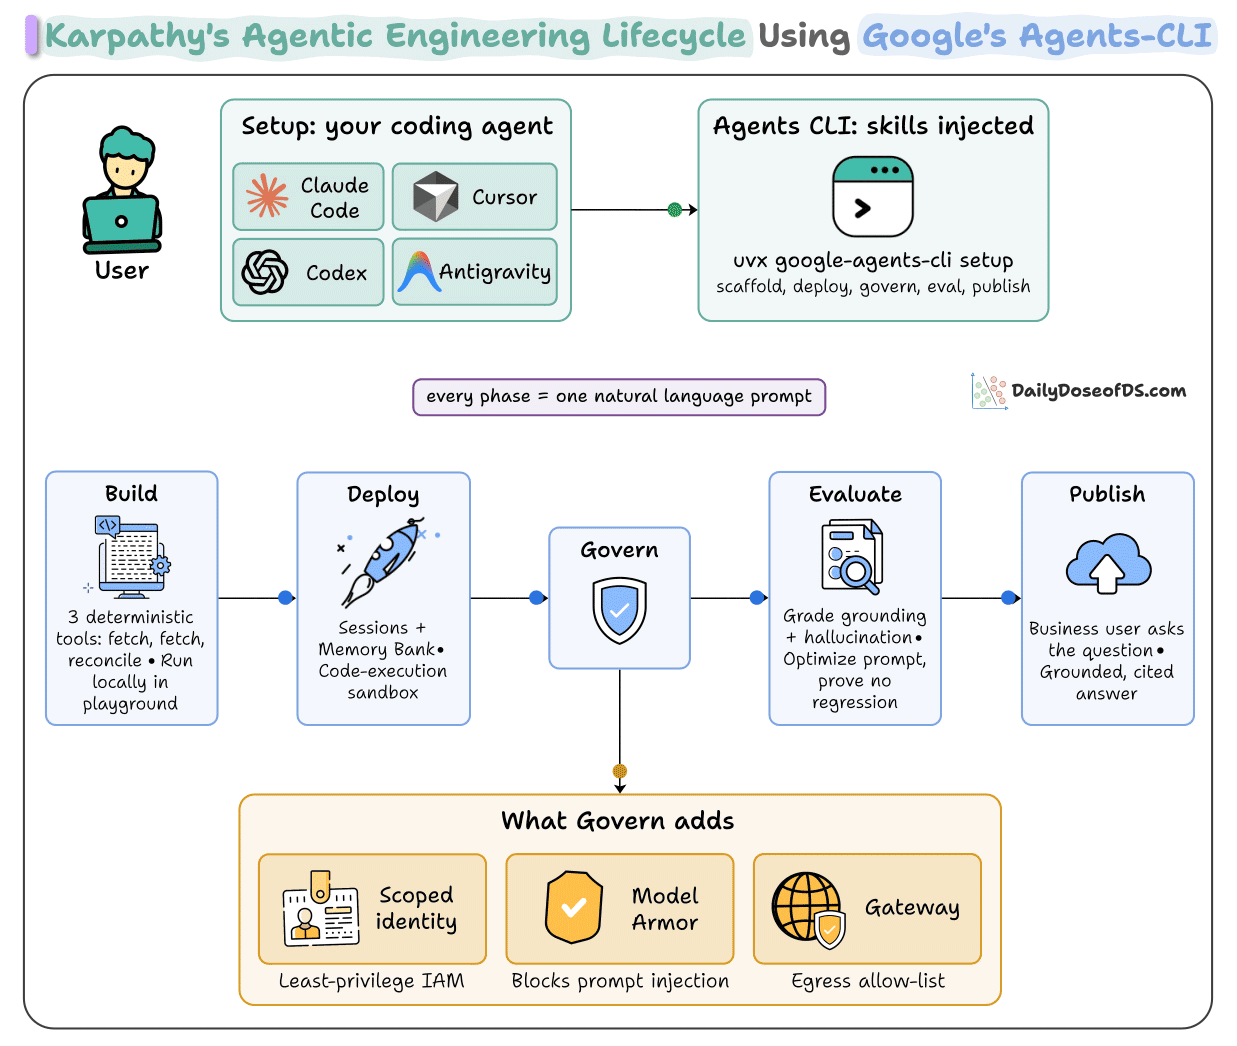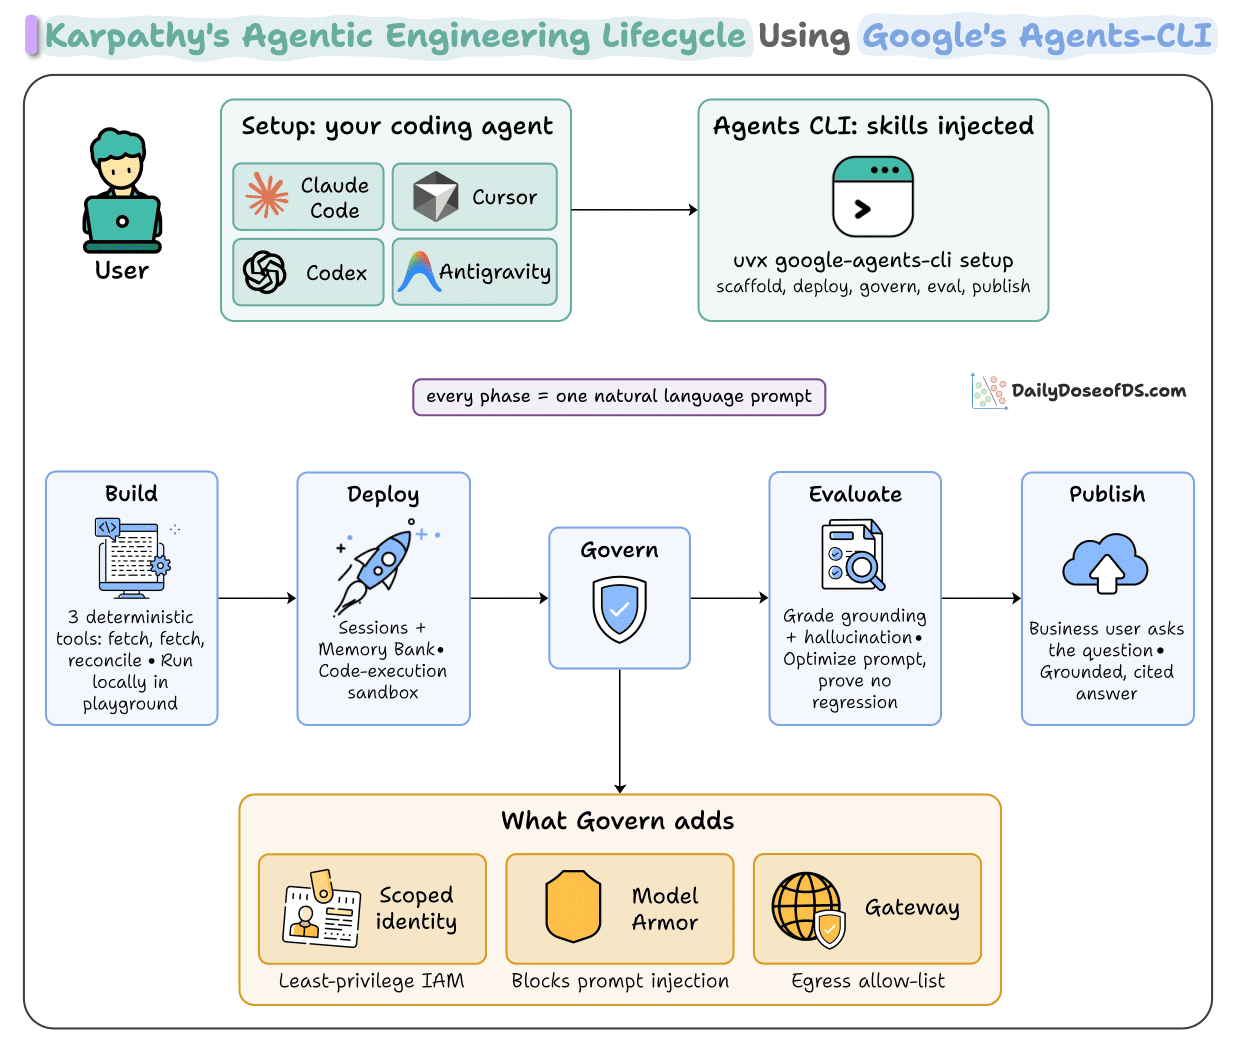
Karpathy's Full Agentic Engineering Lifecycle using Google's Agents-CLI
...explained as step-by-step guide.
Lire
How to Query Billion+ Rows on Postgres Without the Overhead
...explained as a full setup guide.
Lire
A 10-week Roadmap to Run LLMs in Production
...covered with hands-on resources.
Lire