
The Architecture for Serving 100 Fine-Tuned Models on One GPU
...explained with code.
Lire
...explained with code.
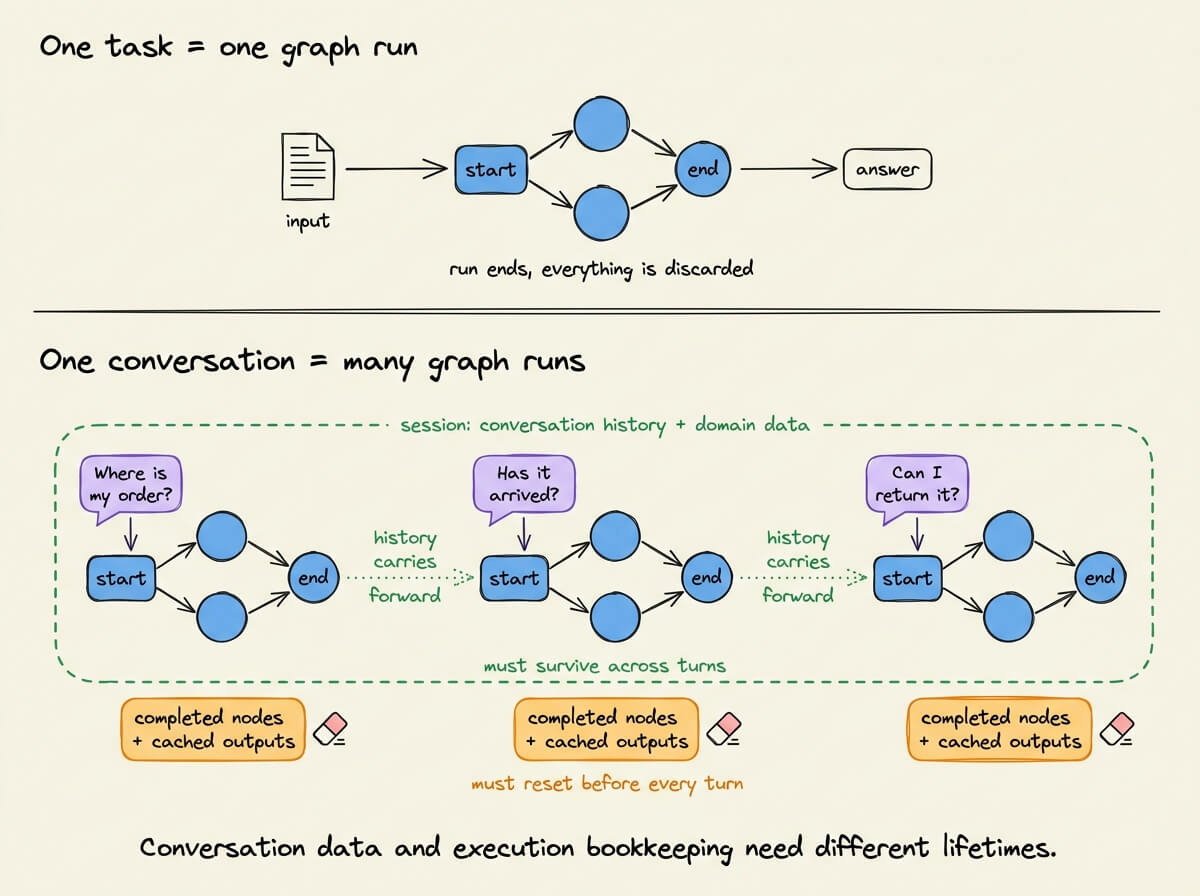
What production agents must preserve between turns, and what they must reset.
A 100% local, open-source guide to recording what AI agents actually do at runtime.
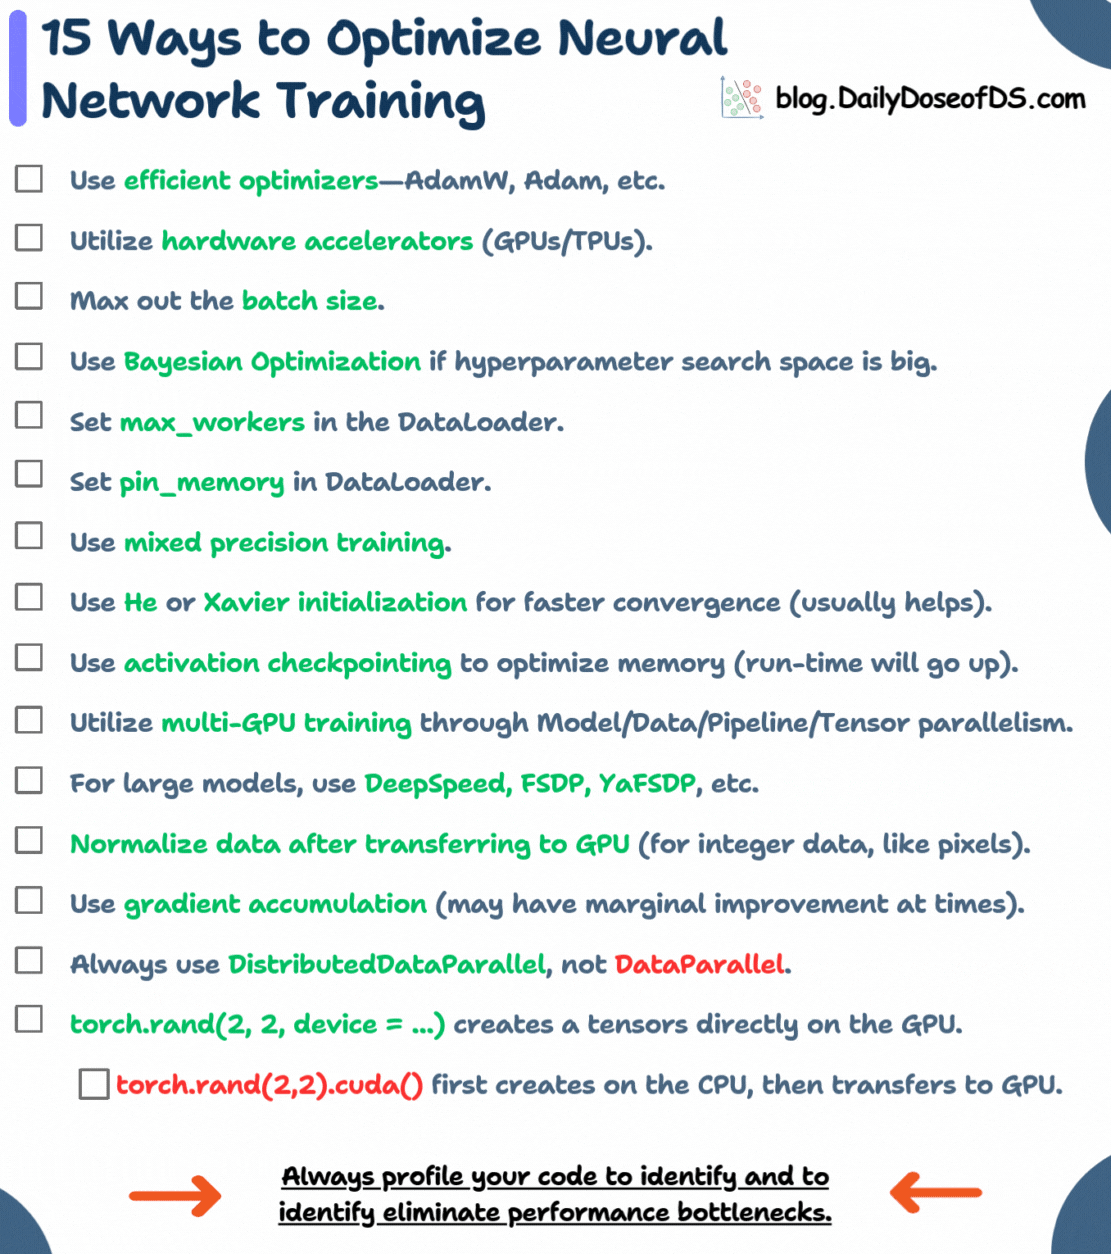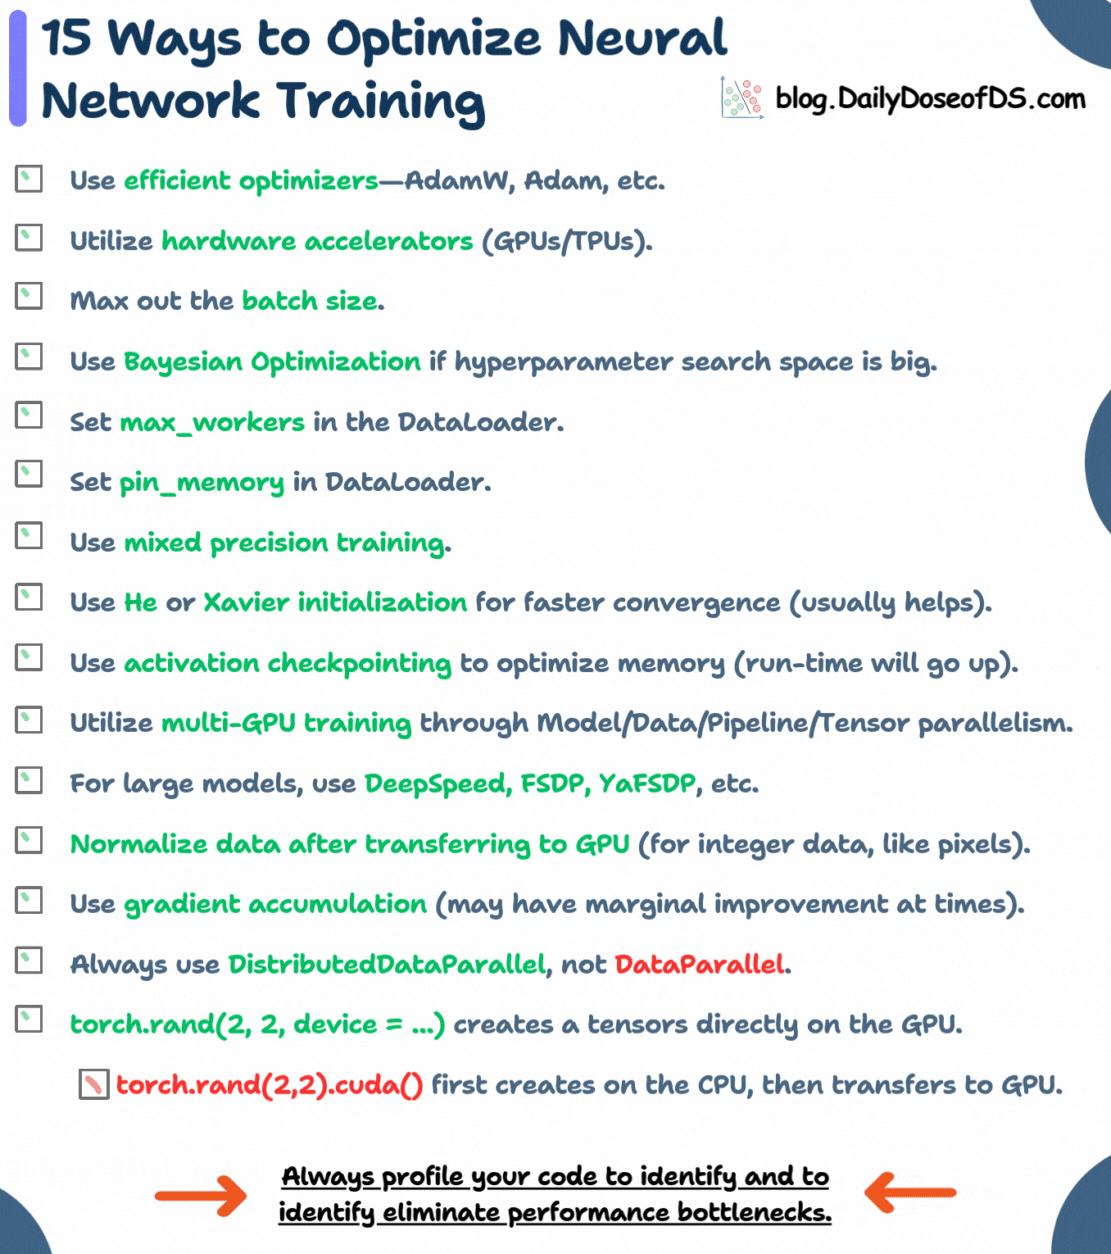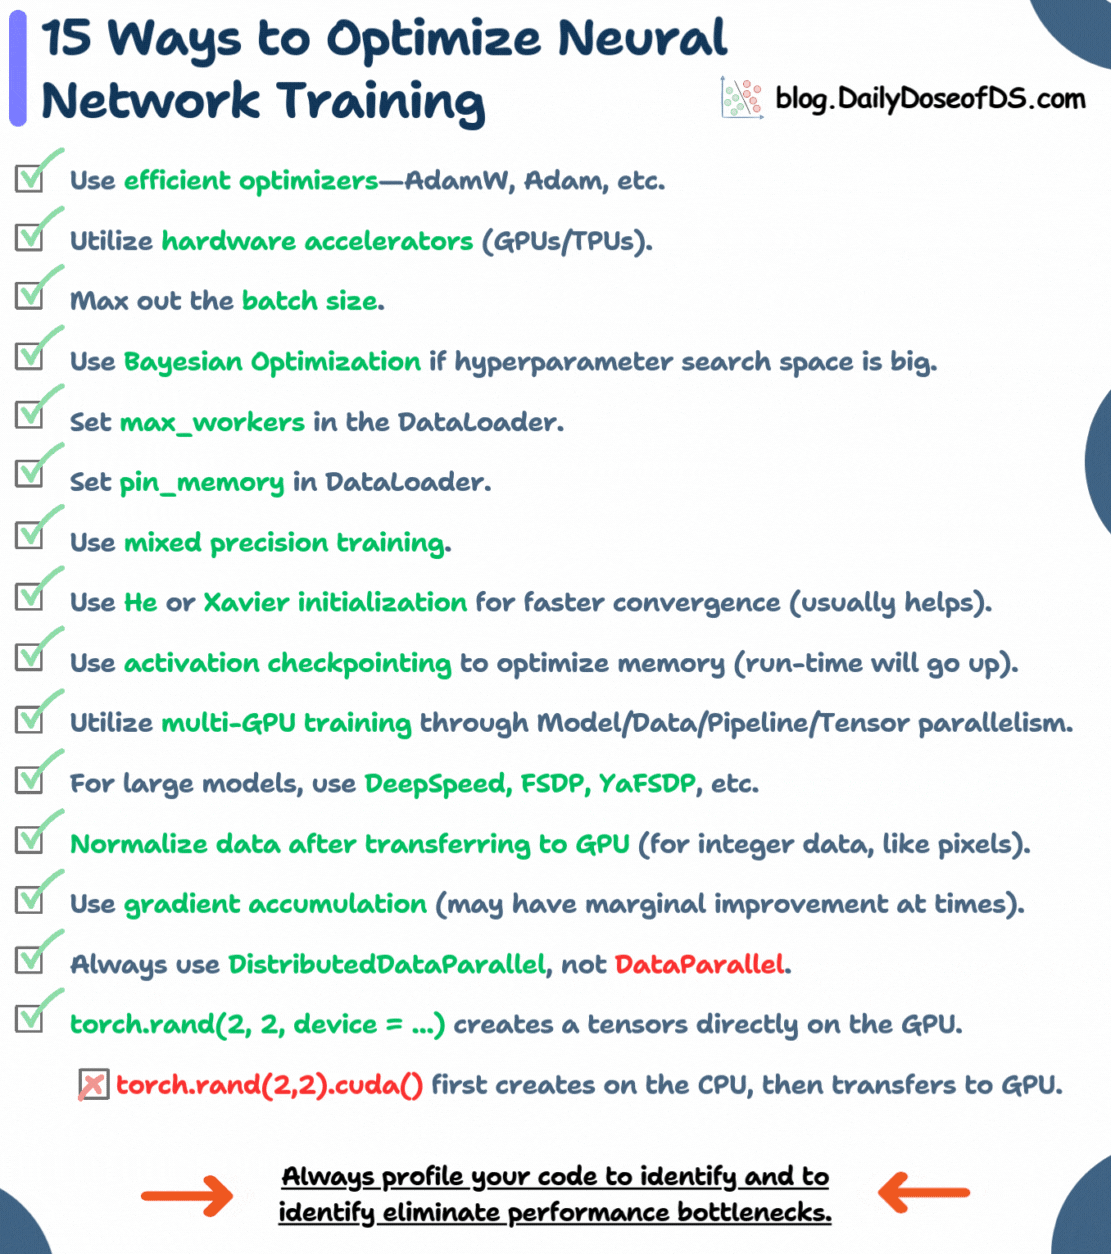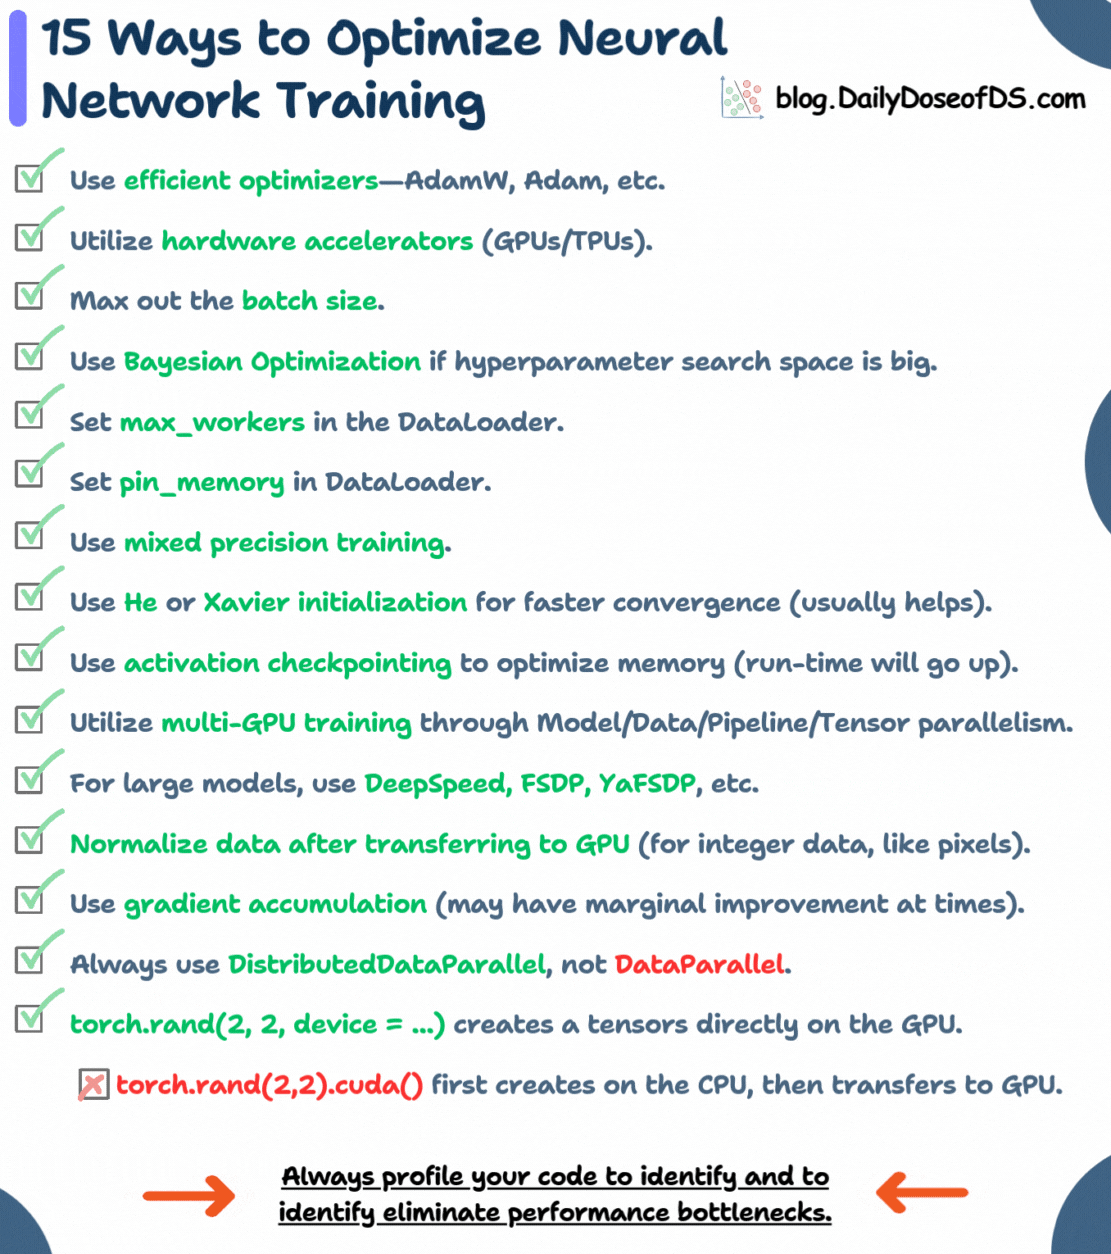
(a popular ML interview question)
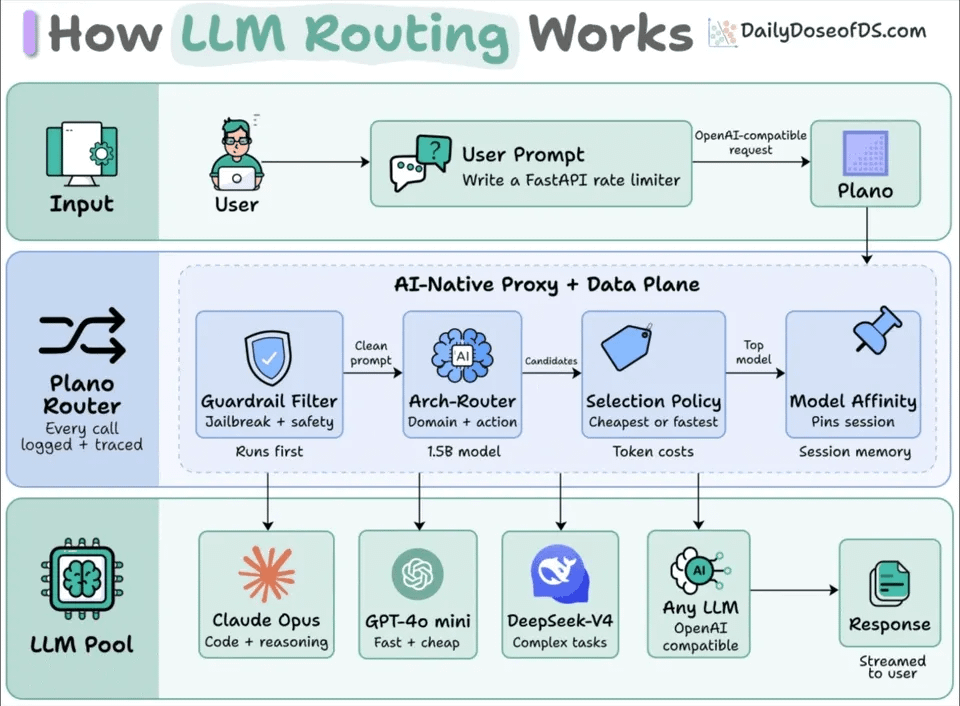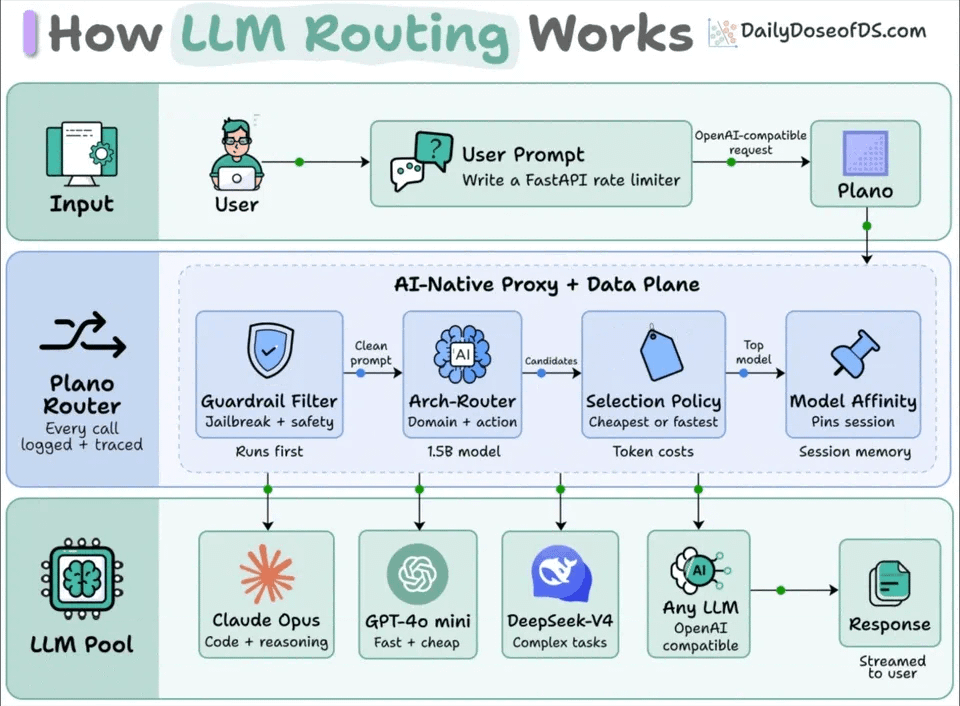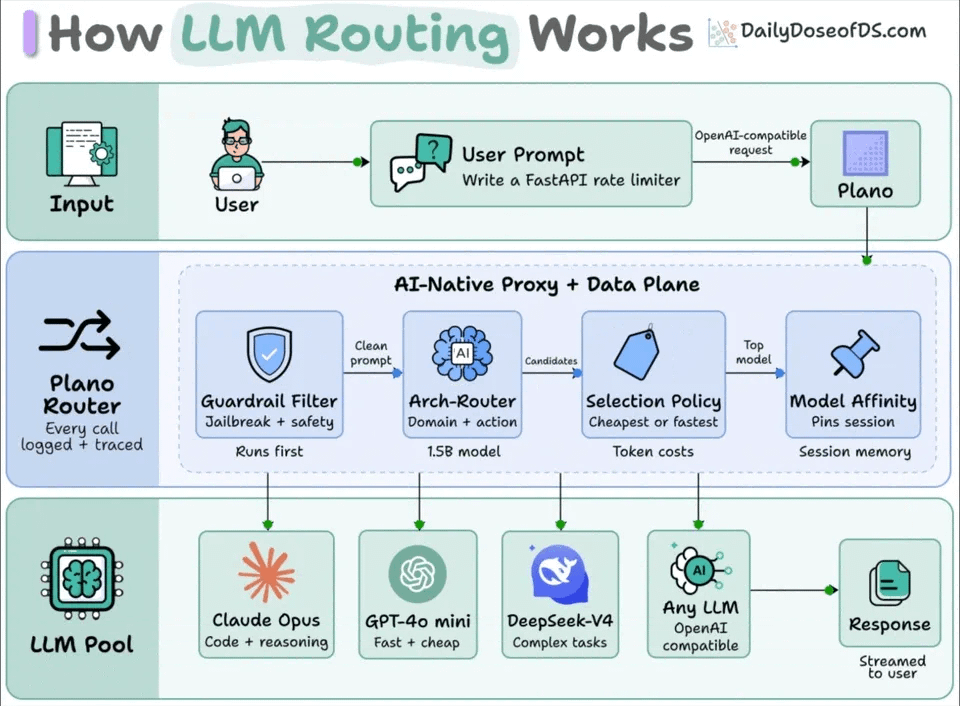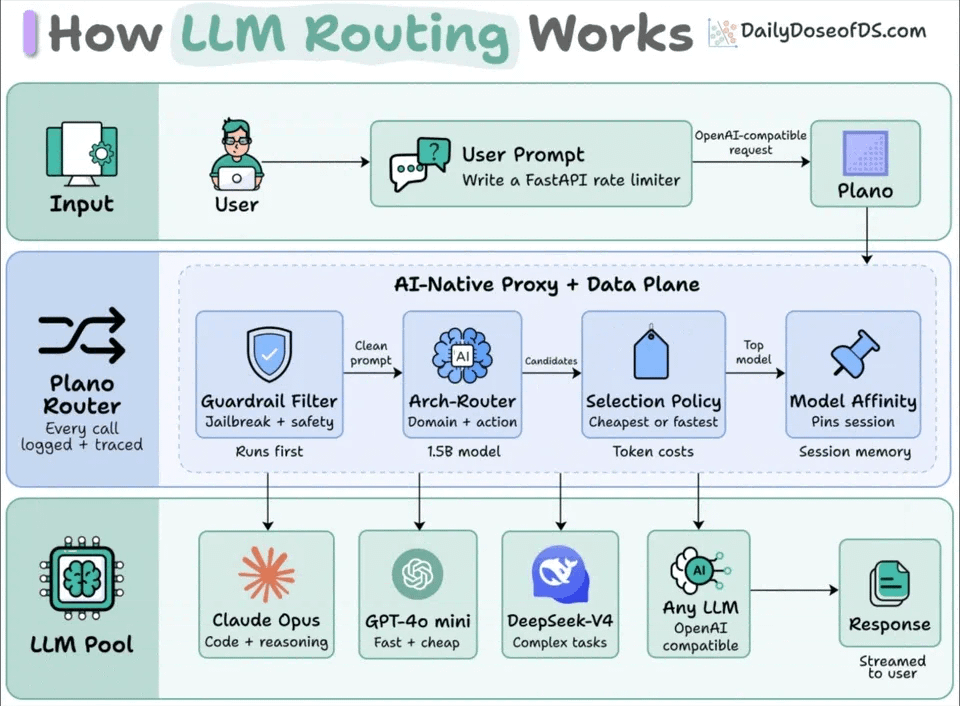
...covered with a production-grade router for LLM apps.
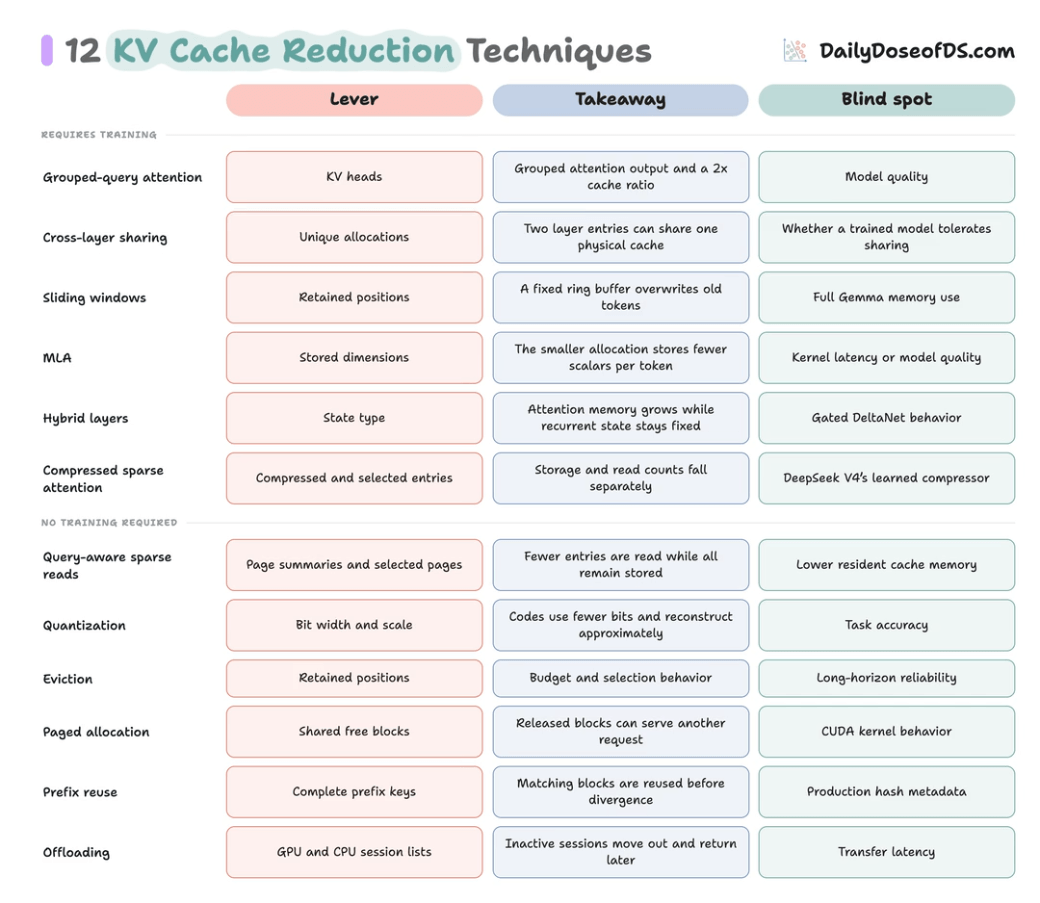
12 techniques to manage KV cache in production.
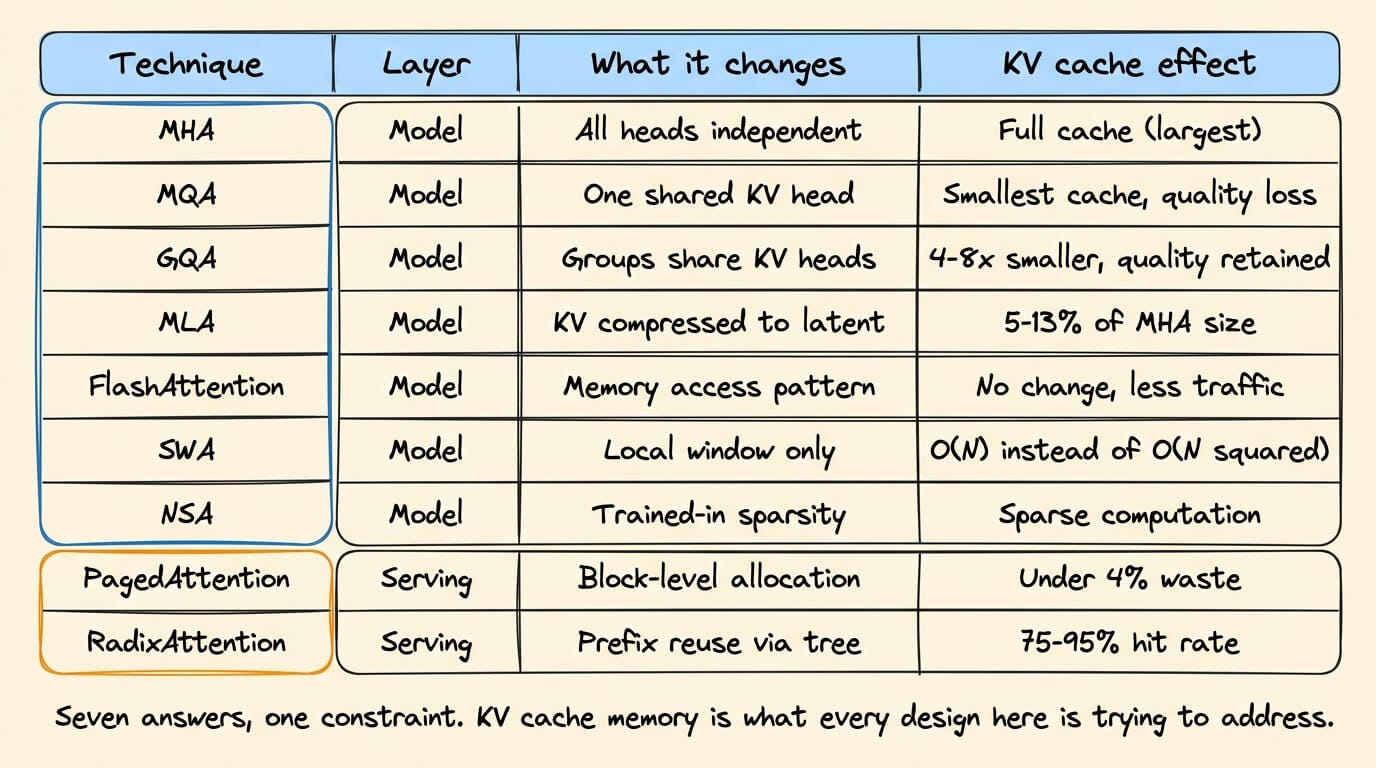
Everything you need to understand how attention works, why the KV cache is the bottleneck, and what every attention variant is actually solving.
A practitioner's guide to local AI.
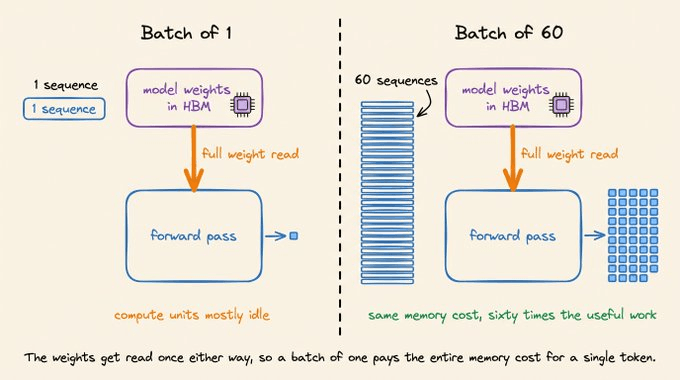
+ a popular LLM interview question.
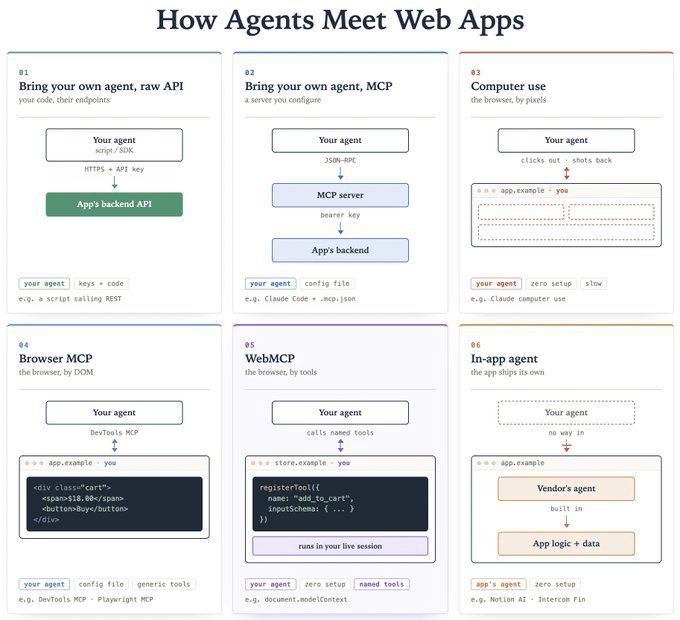
Everything you need to understand WebMCP and expose your site's actions to an agent.
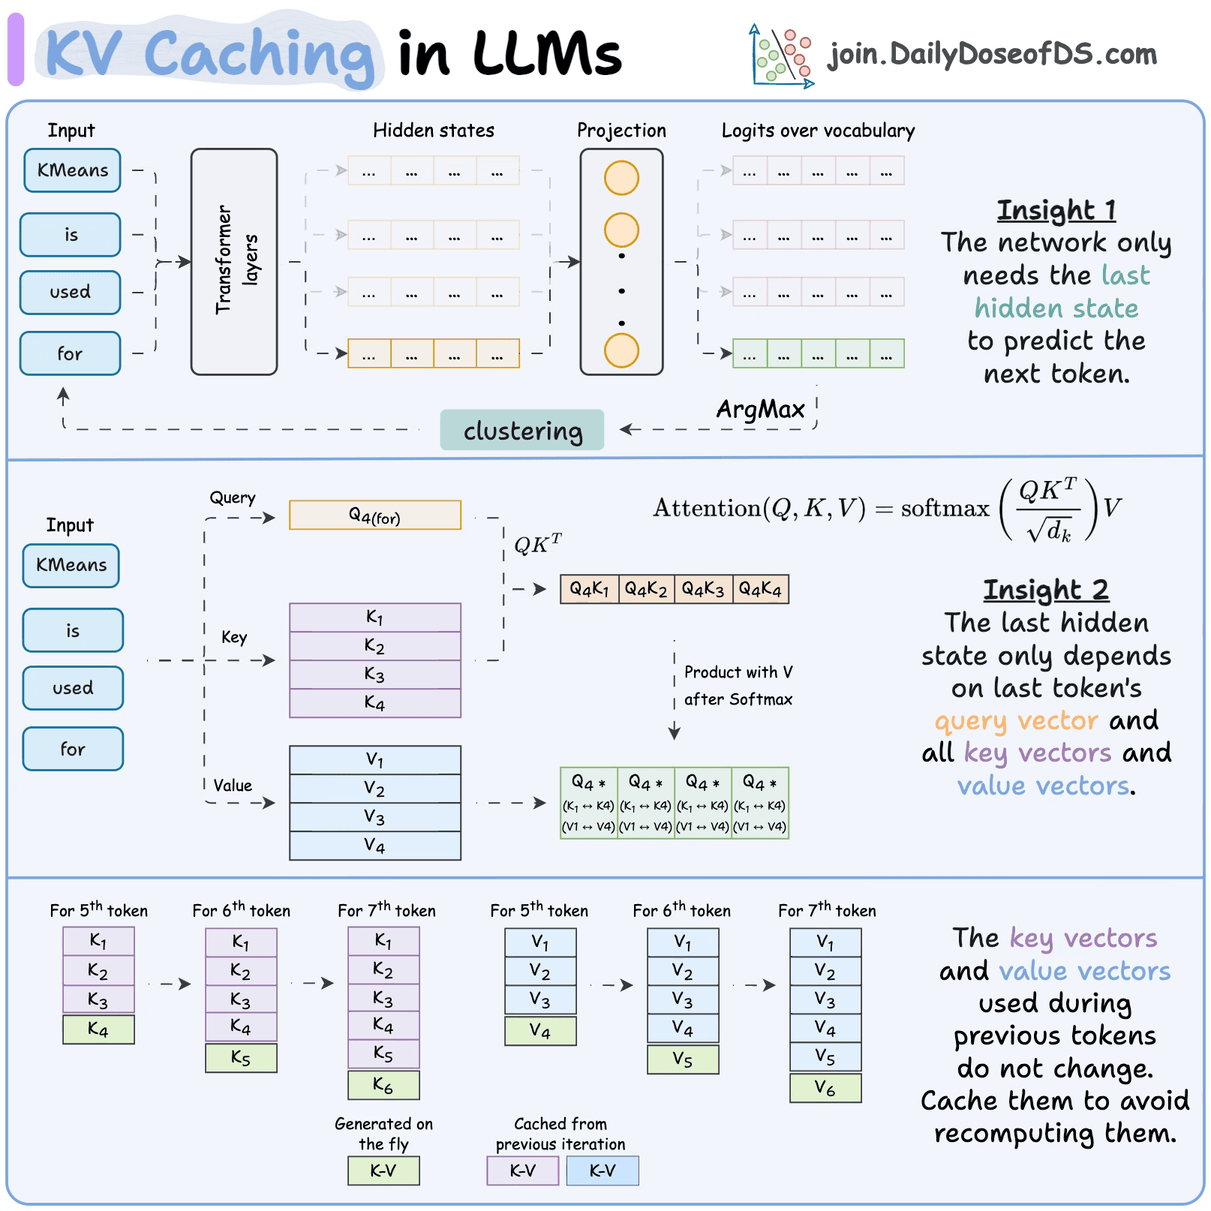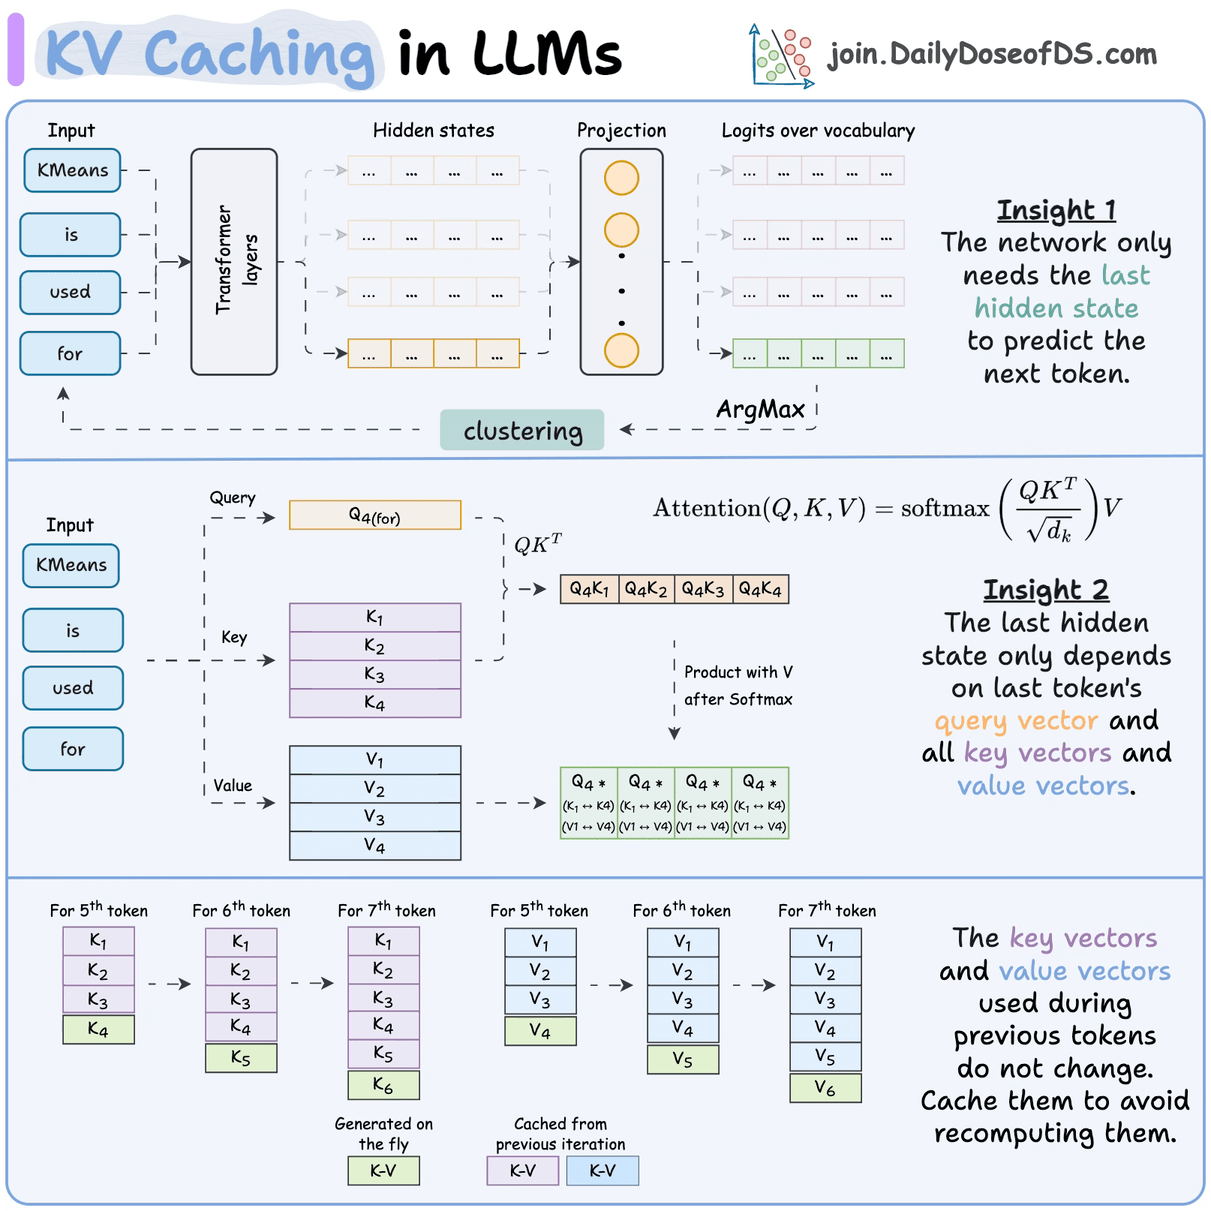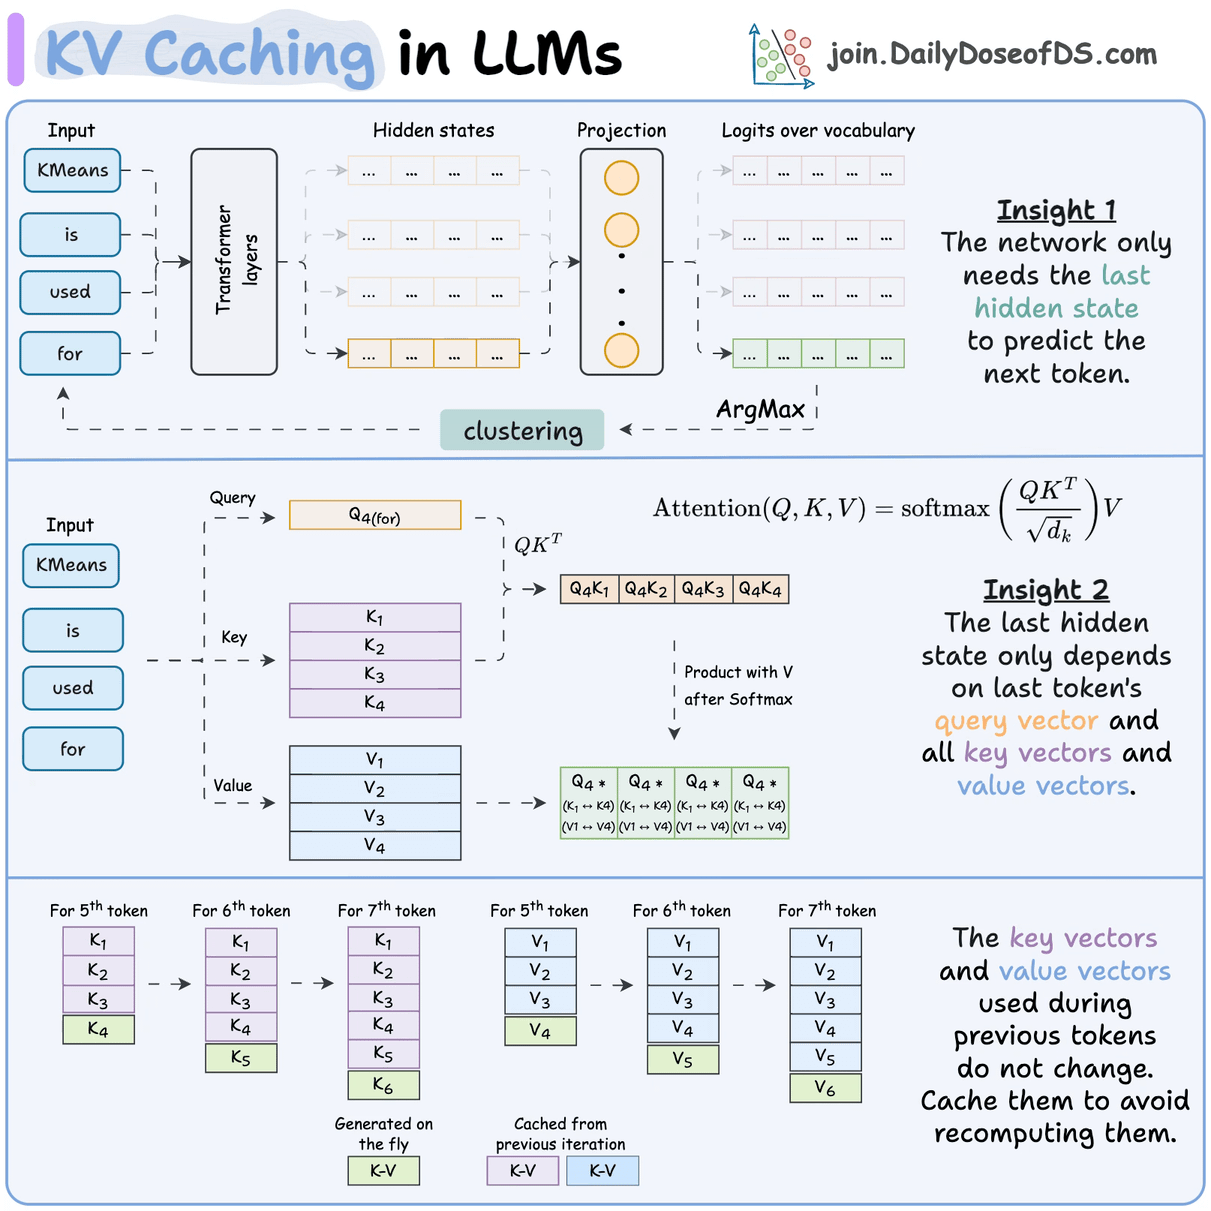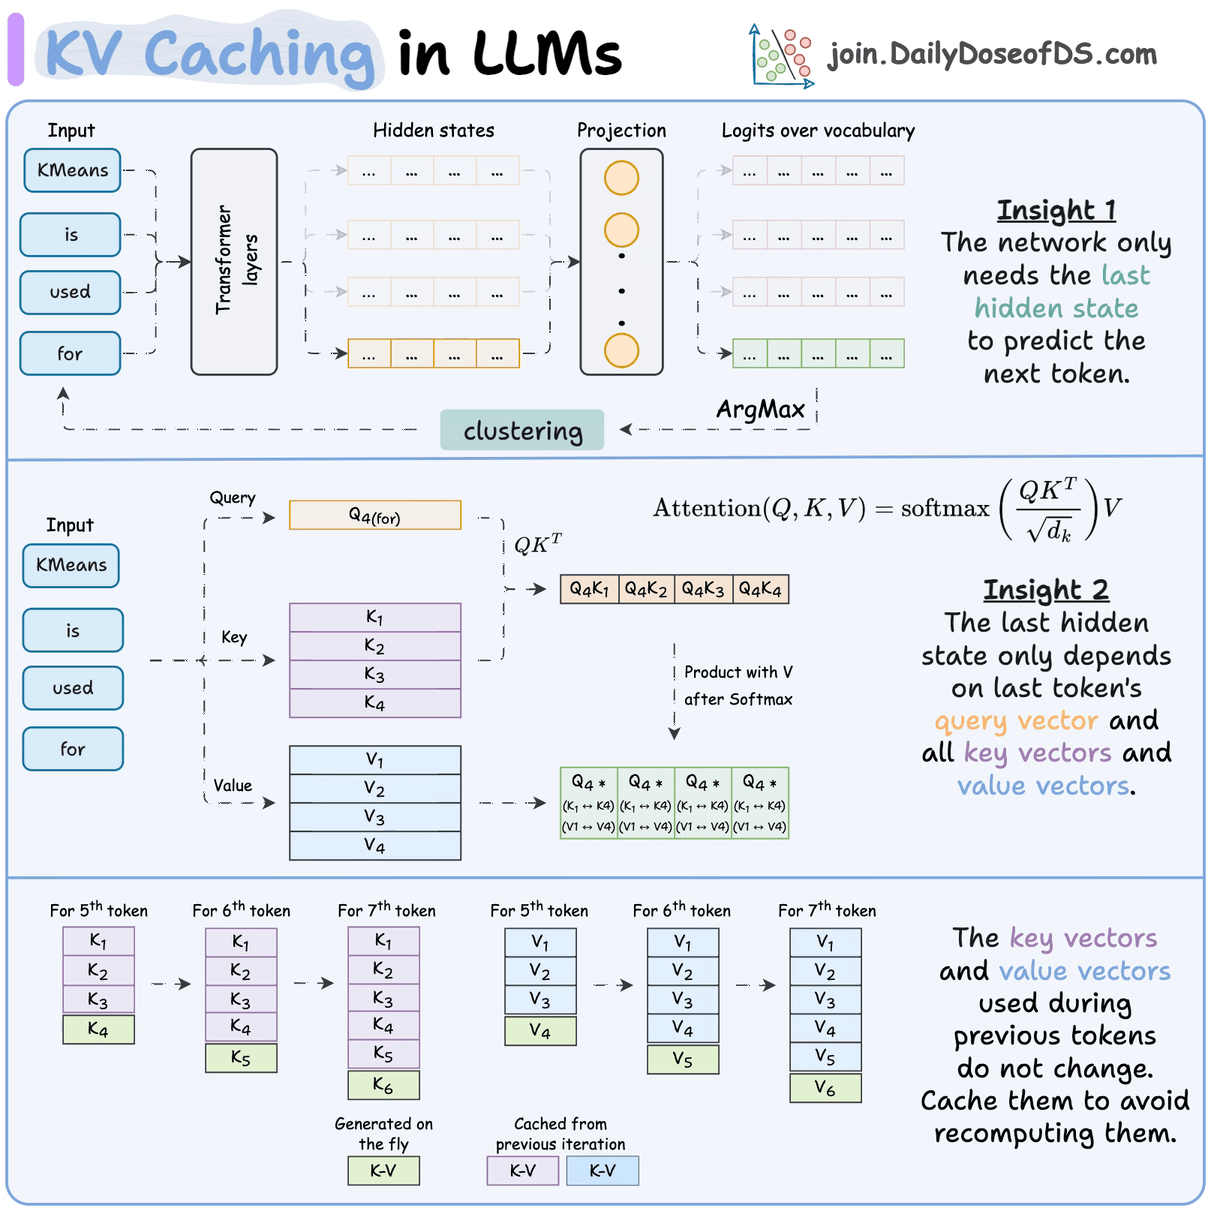
A popular technical LLM interview question.
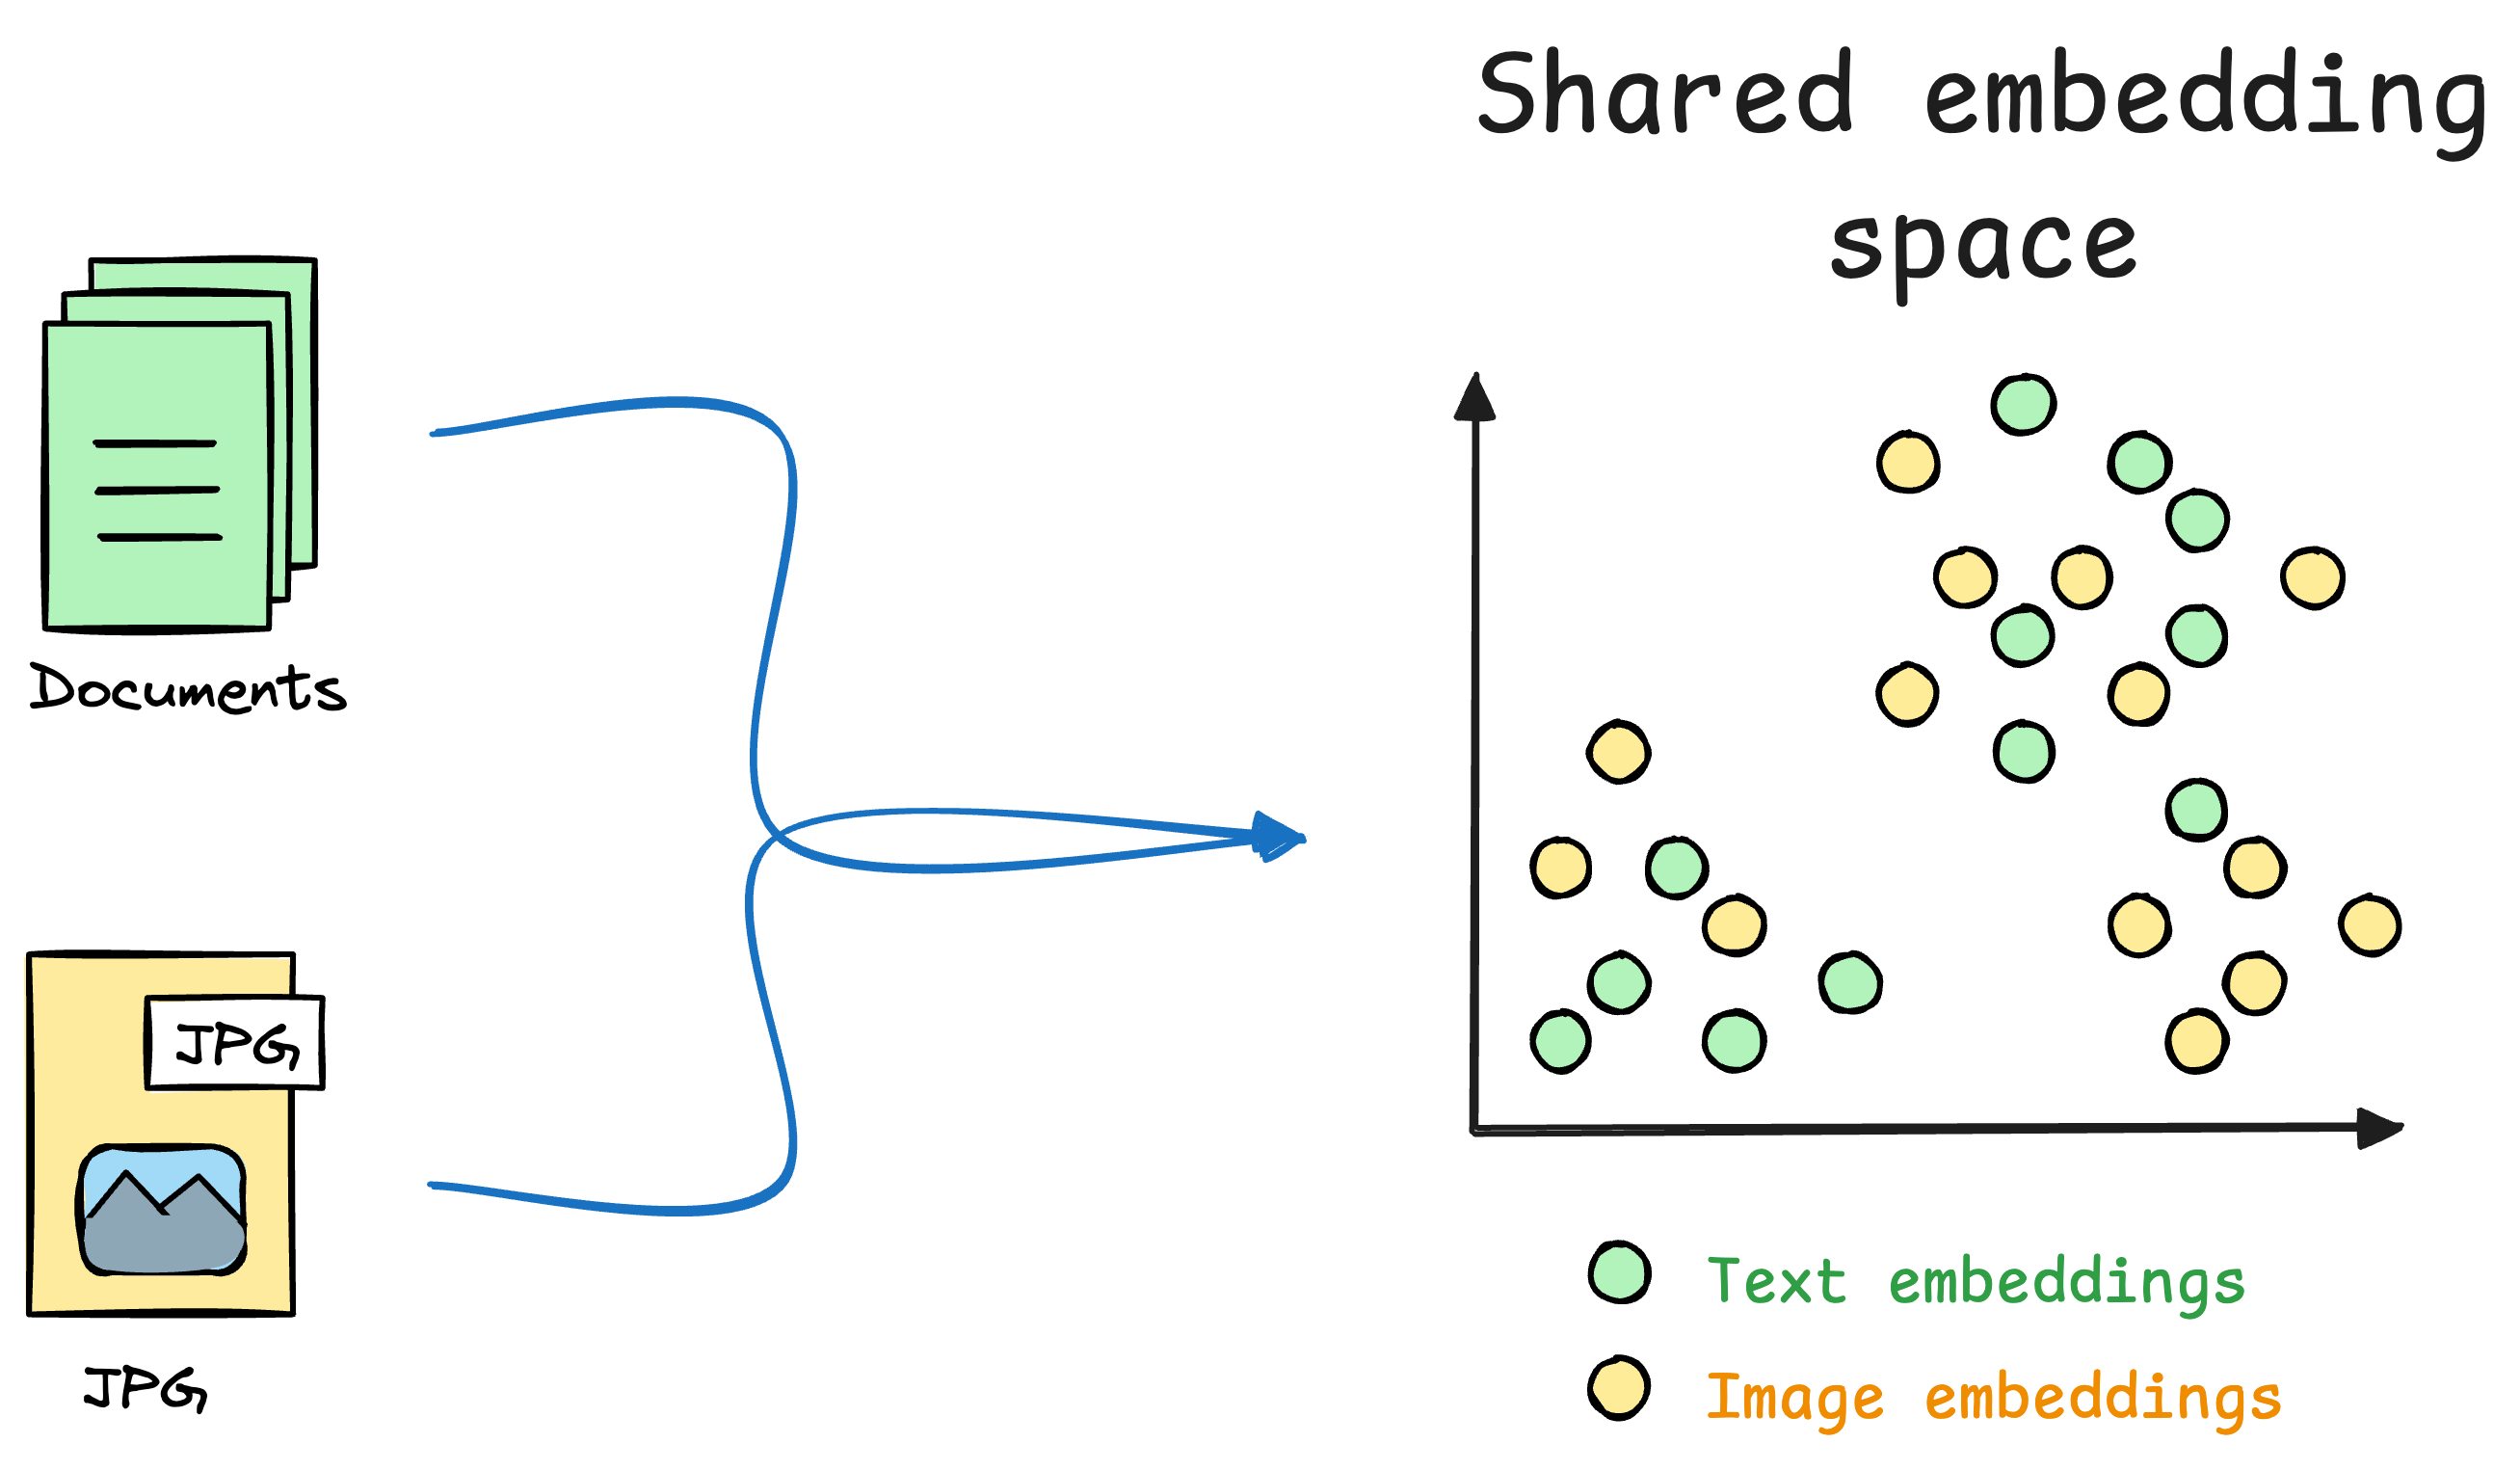
Full guide with code.
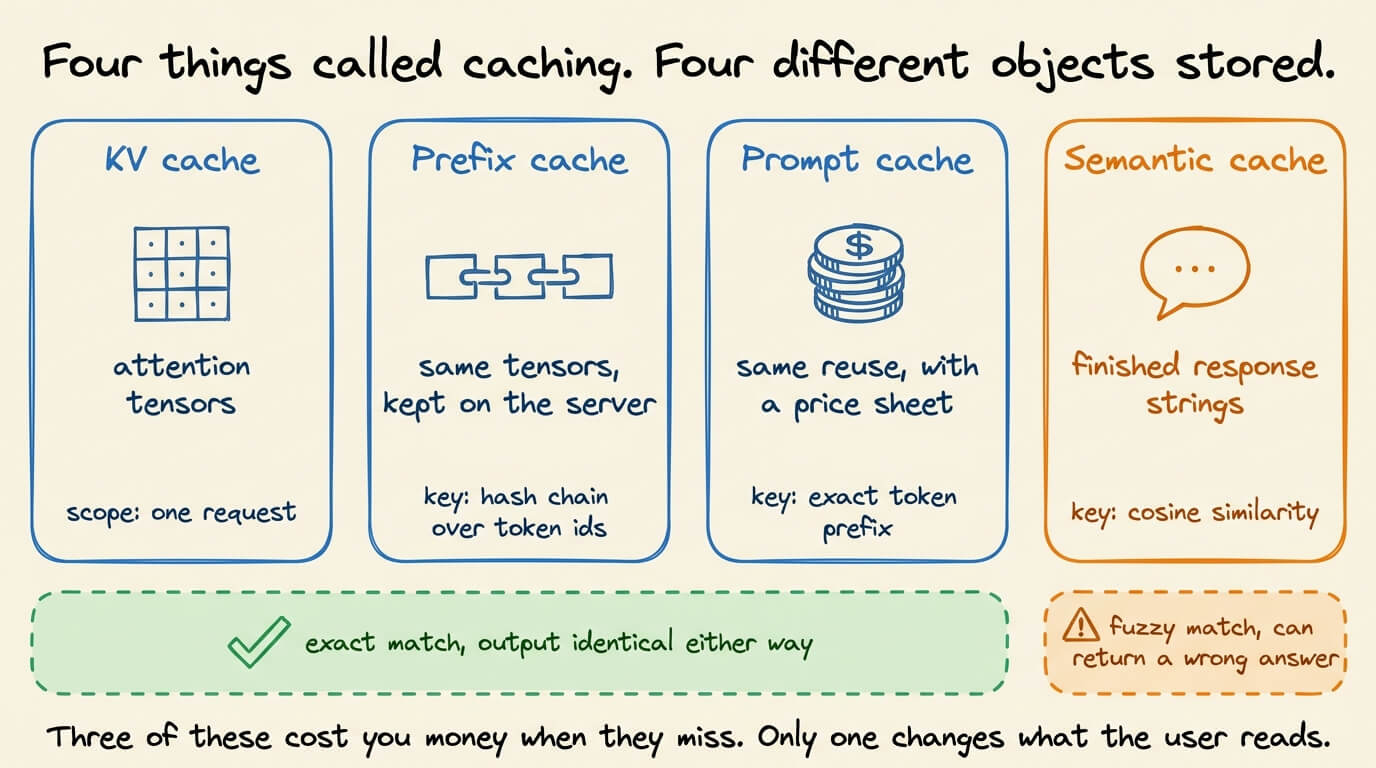
...explained with best practices in production.
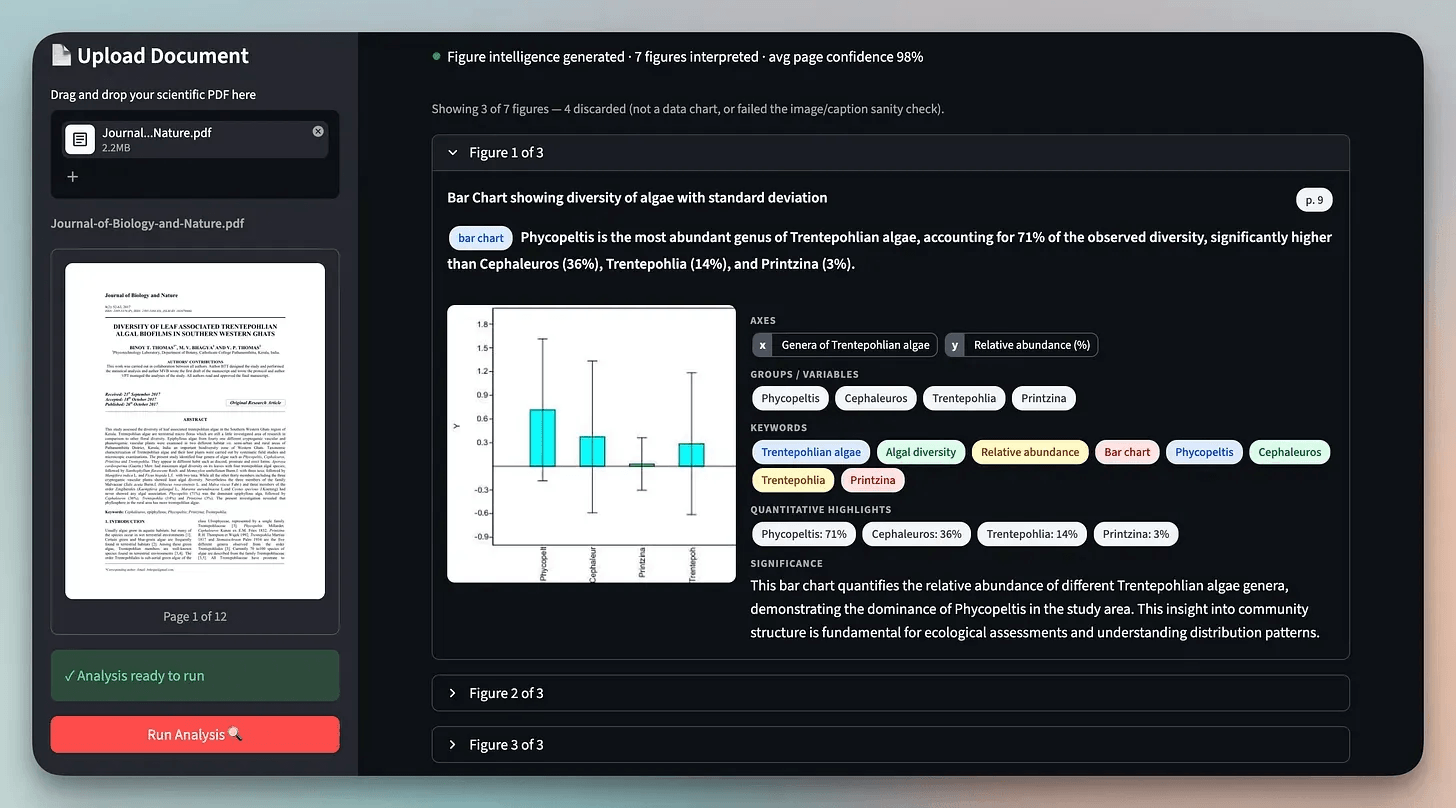
A full walkthrough of the extraction schema, with code.